Every predictive-maintenance vendor quotes an accuracy number, and almost none of them mean much on their own. A model that flags a failure once and cries wolf a hundred times can still post a high "accuracy" on imbalanced failure data — while burning your team's trust with every false alarm. The real question for power generation assets isn't "how accurate is the model," it's "can we act on its alerts?" That takes validation across six dimensions: precision, recall, lead time, false positives, missed failures, and the maintenance outcomes that actually followed. This guide lays out that validation framework, and shows how OXMAINT AI, the AI-powered CMMS, supplies the closed work-order history that turns those metrics from theory into measured fact.
Power Generation · AI & Predictive Maintenance · Model Reliability
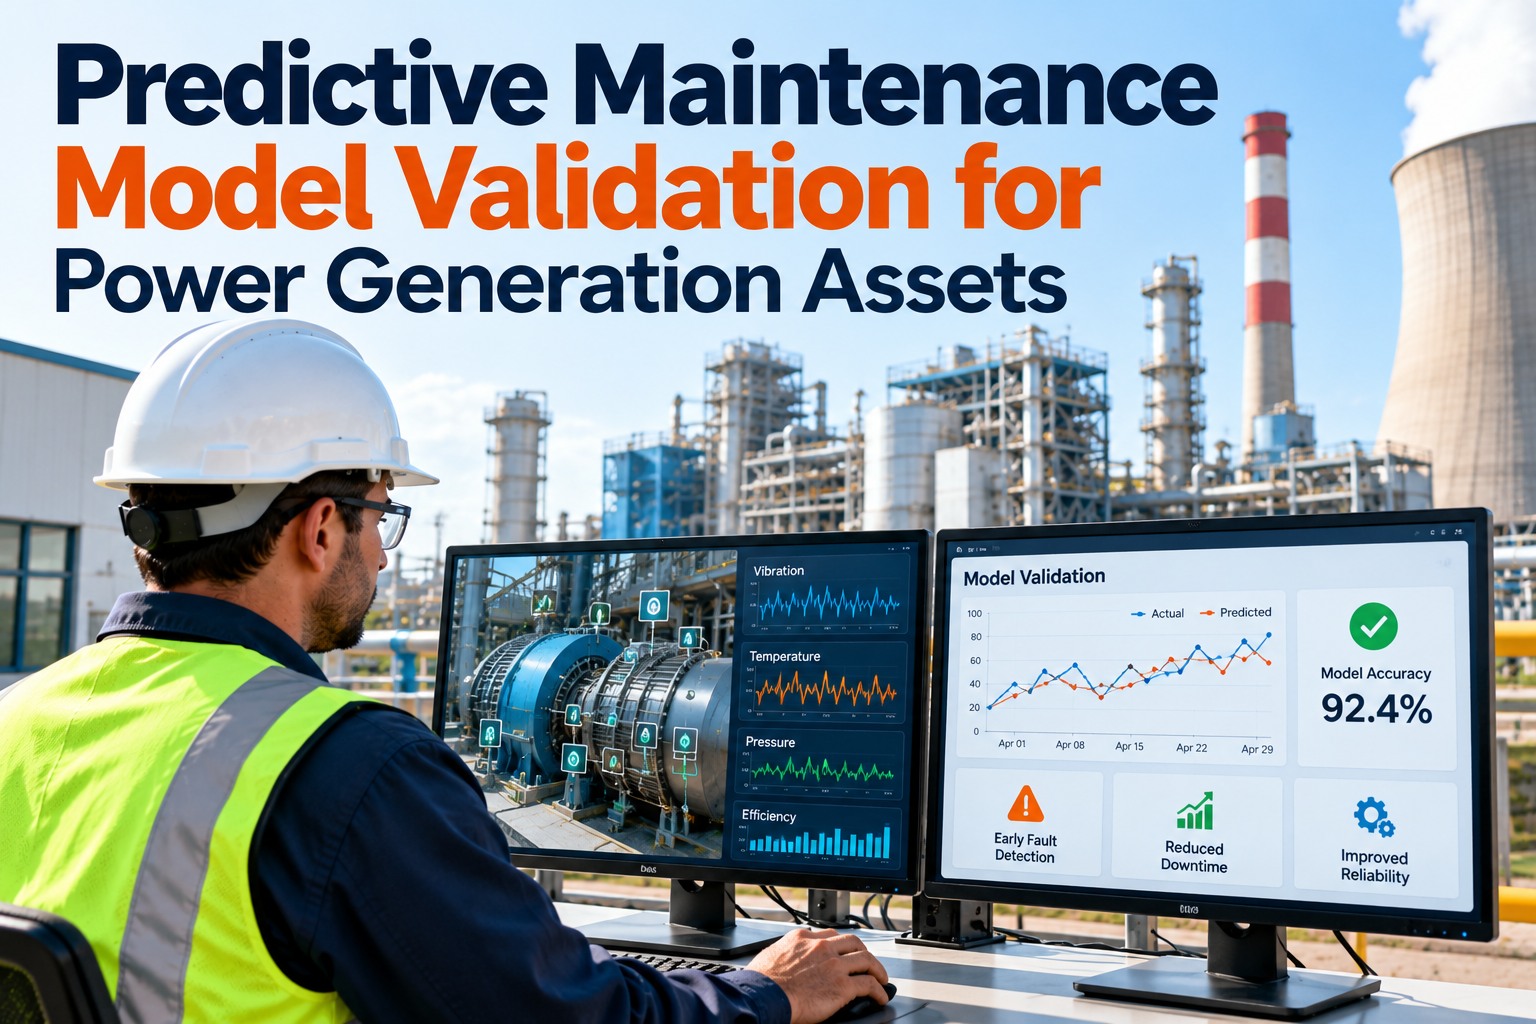
Predictive Maintenance Model Validation for Power Generation Assets
Chasing false alarms and missing the failures that matter? OXMAINT AI runs the workflow in one platform — inspections and predictive alerts become tracked issues, then prioritized work orders, then preventive and predictive schedules. That closed-out history is your validation ground truth: real precision, recall and lead time on your own assets, so you trust the alerts you act on.
6 metrics
precision, recall, lead time, false positives, missed failures, outcomes
Not accuracy
a single number hides false alarms and missed failures on rare-event data
Asymmetric
a missed failure usually costs far more than a false alarm
Ground truth
closed work orders are what make the metrics real, not estimated
Why "99% Accurate" Tells You Almost Nothing
Failures are rare events. If a critical asset fails a handful of times a year, a model that predicts "no failure" every single day is right ~99% of the time — and catches nothing. That's why accuracy alone is the wrong lens for predictive maintenance. What you actually need to know is what happens in the four cells below: when the model raises an alert, and when it stays silent. Start free and score your model against real outcomes in OXMAINT AI.
Failure actually occurred
No failure occurred
Model raised an alert
True Positive
Caught it — alert led to a repair before failure. This is the win.
False Positive
False alarm — a PM done on a healthy asset. Wasted labor and eroded trust.
Model stayed silent
False Negative
Missed failure — the costly one. A forced outage the model didn't warn about.
True Negative
Correctly quiet — healthy asset, no alert. The easy, common case.
On rare-event data the bottom-right cell dominates, which is exactly why accuracy looks flattering. The cells that decide whether a model is usable are the two on the left diagonal — the ones accuracy drowns out.
The Six Validation Metrics That Matter
Read together, these six answer the reliability question a headline number can't. OXMAINT AI supplies the closed-out work-order record each one is calculated from — so they're measured on your assets, not borrowed from a datasheet. Book a demo to see these scored on your own fleet.
Precision
Of the alerts it raised, how many were real?
Low precision means alert fatigue — the team stops trusting the model because most alarms lead nowhere.
Recall
Of the real failures, how many did it catch?
Low recall means the model misses the failures you bought it to prevent — the most dangerous blind spot.
Lead Time
How much warning before the failure?
A correct alert 20 minutes out is nearly useless; the same alert days out is actionable. Lead time is what makes recall valuable.
False Positives
How often does it cry wolf?
Each false alarm is a wasted PM on a healthy asset — and a withdrawal from the team's trust in the system.
Missed Failures
What slipped through silently?
The failures the model never flagged — usually the costliest outcome, and invisible unless you reconcile against actual events.
Maintenance Outcomes
Did acting on alerts actually help?
The bottom line: did validated alerts reduce unplanned downtime and reactive work — or just generate more tickets?
The Trap: The Same Score, Very Different Results
Here's the insight most model reviews miss. Because a missed failure and a false alarm carry wildly different costs, two models with the identical F1 score can produce completely different business results — one saving money, one losing it. You can't validate a power-generation model without weighting its errors by what they actually cost you. Sign up free and weight your model's errors by real cost.
SAME F1 SCORE
Loses money
Trigger-happy: high recall but floods the team with false alarms. Wasted PMs and lost trust outweigh the catches.
SAME F1 SCORE
Breaks even
Balanced on paper, but the errors it makes happen to cancel out — no real gain over the old reactive approach.
SAME F1 SCORE
Saves money
Tuned to the cost of a missed failure vs. a false alarm — catches the expensive ones and keeps false alarms tolerable.
The same headline metric maps to a loss, a wash, or a real saving depending on how the model's errors line up with your costs. Validation for power generation has to account for that asymmetry — a missed turbine or boiler event is not the same size of mistake as one extra inspection.
You Can't Validate a Model Against Data You Don't Have.
Real precision and recall need a trustworthy record of what actually failed and what didn't. OXMAINT AI is where alerts, inspections and confirmed outcomes are closed out on the asset — the ground truth every validation metric is built from.
Lead Time Is a Tradeoff, Not a Bonus
It's tempting to want the earliest possible warning, but lead time cuts both ways. Push the prediction window too far out and the model fires on noise and replaces healthy components; keep it too tight and there's no time to plan the repair. The right window sits where the warning is early enough to act on but late enough to be confident. Book a demo to tune lead time against your planning needs.
Too early
Fires on noise, flags failures that may never happen — premature replacements and more false positives.
Right window
Enough warning to plan the repair into an outage, with enough signal to be confident the alert is real.
Too late
Technically a correct prediction, but no time to act — the alert arrives as the asset is already failing.
How the CMMS Closes the Validation Loop
Validation isn't a one-time test — it's continuous. Every alert should be reconciled against what actually happened, and that reconciliation lives in the work-order record. Here's how OXMAINT AI turns day-to-day maintenance into an always-current validation dataset. Start free and close the validation loop in OXMAINT AI.
Alert
Model raises an alert on an asset — logged with its timestamp and predicted failure mode against that exact unit.
Inspect
A work order sends someone to check — the inspection confirms a real developing fault, or clears the asset.
Label
The outcome is closed out — true positive or false alarm, recorded on the asset with the finding as evidence.
Reconcile
Unflagged failures are captured too — any breakdown with no prior alert becomes a recorded missed failure.
Measure
Precision, recall and lead time recompute from the closed record — validation that stays current as the fleet runs.
Frequently Asked Questions
Isn't a high accuracy score good enough?
Not for predictive maintenance. Failures are rare, so a model can score high on accuracy while catching almost nothing — it's simply right that "no failure" happens most days. Precision, recall and missed-failure counts tell the real story.
Start free and score your model beyond accuracy.
Which matters more, precision or recall?
It depends on cost. On critical generation assets, a missed failure usually costs far more than a false alarm, so recall is often weighted higher — but too little precision creates alert fatigue that undermines the whole program. You validate both, weighted by what each error costs you.
Book a demo to weight your metrics by cost.
How do we even know our real failure rate to measure recall?
From your closed work orders. Every confirmed failure and every false alarm has to be recorded against the asset — that reconciled history is the ground truth recall is calculated from. Without it, recall is a guess.
Sign up free and build that history in OXMAINT AI.
What's a good prediction lead time?
Long enough to plan the repair into a window, short enough to stay confident the alert is real. There's no universal number — it's a tradeoff you tune against how long your planning and parts lead times actually are.
Book a demo to tune lead time to your operation.
Do we validate once, or keep validating?
Continuously. Assets age, operating conditions shift, and a model that validated well last year can drift. Because every alert and outcome is closed out in OXMAINT AI, the metrics stay current instead of frozen at deployment.
Start free and keep validation live.
Trust the Alerts You've Actually Validated.
Move past headline accuracy — measure precision, recall, lead time, false positives, missed failures and real outcomes against the closed work-order history in OXMAINT AI, and deploy models your team can trust.