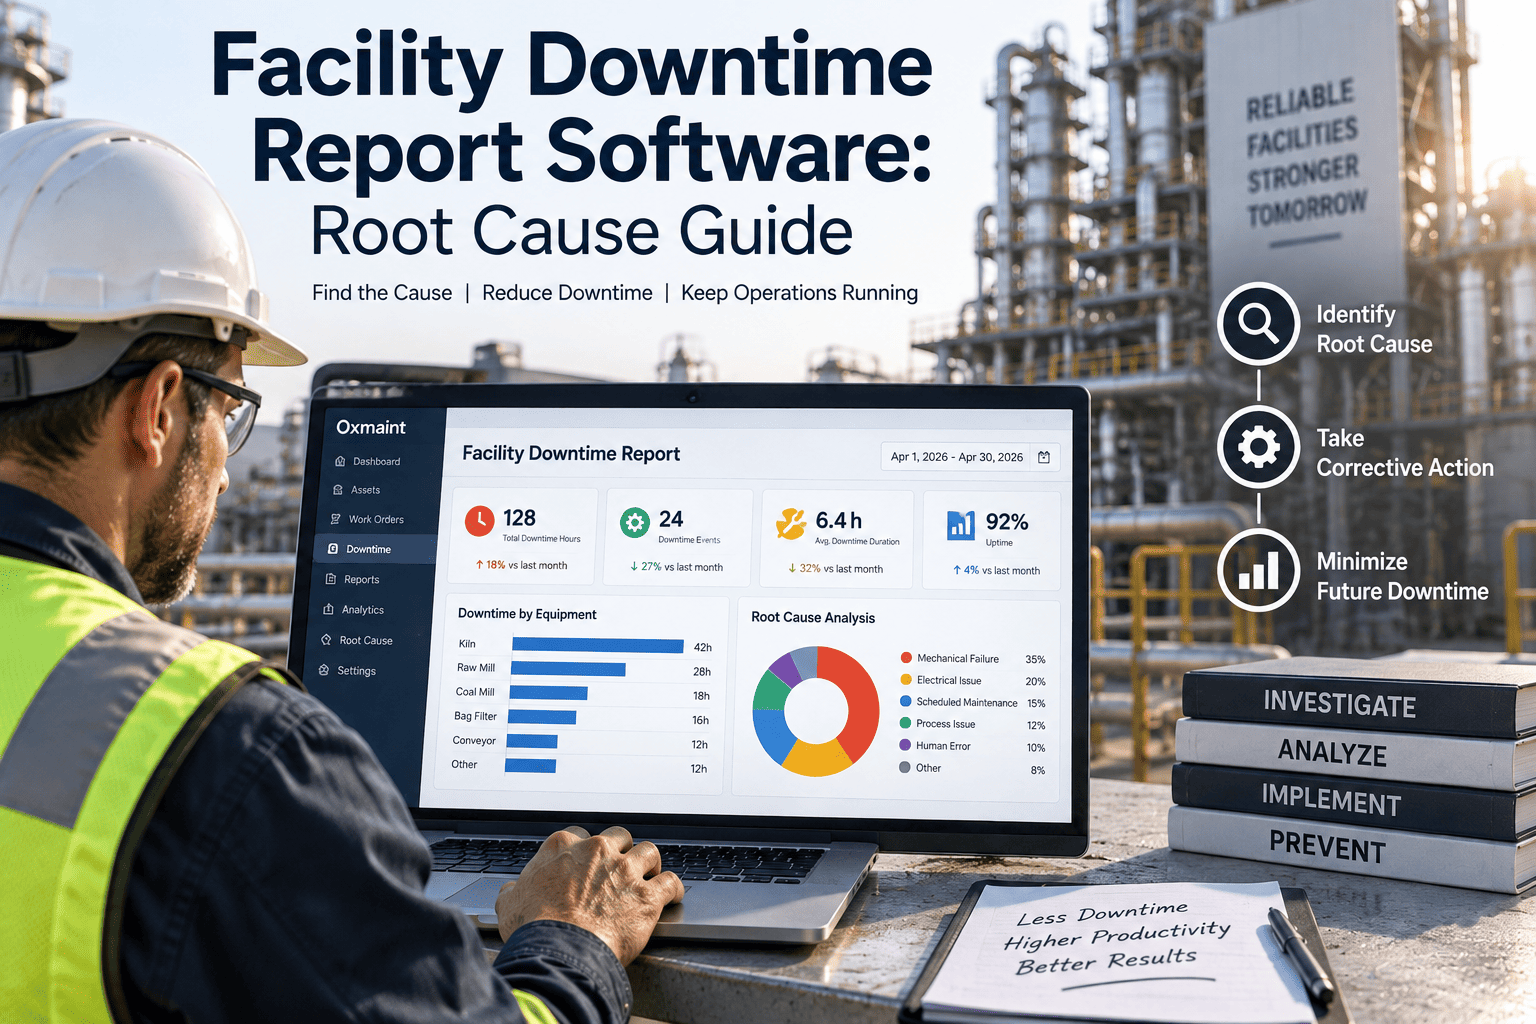
Most facility downtime reports answer the wrong question. They tell you a chiller was down for four hours on a Tuesday, but they don't tell you whether that's the third time this quarter or the first time in two years — and that distinction is the entire difference between a one-off event and a pattern worth fixing. A downtime report built inside a CMMS exists to close that gap, turning stop-and-start timestamps into a traceable root cause instead of a line item nobody revisits.
A downtime log tells you what happened. A root cause report tells you why it keeps happening.
Structured reason codes, root cause tracking, and Pareto-ranked reporting turn scattered downtime entries into a findable pattern — so the same failure stops repeating every few months.
Downtime that never gets traced back to a cause repeats itself, quietly, for years
A single unplanned equipment failure rarely bankrupts a facility budget on its own. What actually erodes it is the same failure mode recurring across an asset fleet because nobody connected event four to events one through three. Facility teams that log downtime without structured reason codes routinely discover, only after pulling a year of records, that a handful of assets account for most of their unplanned hours.
Why "miscellaneous" becomes the biggest category in most downtime reports
Ask most facility teams to pull last quarter's downtime report and a large share of the entries will fall under a vague catch-all: "equipment issue," "process," or simply "other." That's not a data entry failure so much as a design failure in how the reporting was set up to begin with. A technician standing next to a stopped chiller at 2am is not going to stop and write a paragraph explaining the failure mode. They're going to write the fastest thing that gets the ticket closed, and if the system doesn't give them an easy, specific option to choose, "equipment issue" is what gets logged every time. Fixing that starts with the structure of the reporting tool, not with asking people to type more carefully.
No constrained reason-code list
Free-text entry fields let technicians write whatever's fastest under pressure, which almost never matches the wording used the last time the same asset failed.
Work orders close before the cause is known
The moment equipment restarts, the ticket gets closed. The actual failure mode investigation, if it happens at all, occurs off-system and never makes it back into the record.
Micro-stops go uncaptured
Short stoppages under a few minutes are frequently skipped entirely on manual logs, even though they often add up to more lost hours than the rare major failure.
No link between the report and the fix
Even when a root cause is identified, the corrective action often lives in a separate email thread or meeting note instead of being tracked to closure in the same system.
Downtime data quality is decided in the first ninety seconds of a stop
How an event gets captured at the moment it happens determines whether it becomes usable data later. Facility teams generally rely on a layered capture model rather than a single method.
| Capture Method | How It Works | What It Catches | Limitation |
|---|---|---|---|
| Sensor / BMS integration | Building or asset controls feed status changes directly into the CMMS | Every stop above a configured threshold, timestamped automatically | Needs an integrated BMS or IoT layer to exist first |
| Guided technician entry | Technician selects from a constrained reason-code tree on a mobile device | Context a sensor can't infer, like "manually isolated for inspection" | Only as good as the reason-code list it's built on |
| Work order closeout RCA | Root cause and corrective action attached when the ticket is closed | The actual failure mode, not just the symptom | Easy to skip under time pressure without an enforced field |
A starting reason-code structure for facility downtime
Every facility eventually customizes its own taxonomy, but most build from the same core categories below, arranged from equipment-level causes through process and human factors.
| Category | Example Cause | Typical Fix |
|---|---|---|
| Component wear | Bearing, belt, or seal degradation past service life | Condition-based PM triggered by trend, not calendar |
| Control or sensor fault | Drifted setpoint, failed sensor, miscalibrated controller | Scheduled calibration and sensor health checks |
| Process or load condition | Equipment run outside rated capacity or duty cycle | Operating procedure review, load rebalancing |
| Installation or spec error | Component under-rated for actual operating conditions | Spec correction on next replacement cycle |
| Human factor | Missed inspection step, incorrect restart sequence | Checklist redesign, refresher training |
The four-stage path a downtime event needs to travel
Capture
Every stoppage, including micro-stops, is timestamped and tagged by reason code at the moment it happens.
Rank
Events are aggregated into a Pareto view, surfacing which asset or cause is actually driving the most lost hours.
Investigate
A structured RCA — 5-Why or fishbone — is triggered for repeat or high-impact events before the ticket closes.
Close The Loop
The corrective action is tracked as its own work order and checked at the next PM cycle to confirm it held.
The numbers a root cause program lives or dies on
A downtime report full of reason codes still isn't useful until it's summarized into metrics a reliability team can track over time. Two of them carry most of the weight. Mean Time Between Failures, or MTBF, tracks how often a given asset fails — and whether that interval is getting longer as corrective actions take hold, or staying flat despite repeated repairs. Mean Time To Repair, or MTTR, tracks how quickly the team responds once a failure does occur, which is where dispatch delays, missing parts, and unclear procedures tend to show up. Facilities that only watch total downtime hours often miss which of these two numbers is actually driving the trend, and end up investing in the wrong fix — adding staff to speed up repairs, for instance, when the real problem is a component that keeps failing in the first place.
MTBF Rising
A widening interval between failures on the same asset is the clearest sign a corrective action is actually holding.
MTTR Falling
Faster repair times usually trace back to better parts availability, clearer procedures, or earlier detection — not luck.
Repeat Rate
The share of failures on an asset that match a prior failure's root cause is the single best indicator of whether RCA is closing the loop.
Why more downtime reporting is moving from spreadsheets to live dashboards
Downtime reporting used to mean a monthly spreadsheet assembled from paper logs, usually arriving well after the events it described were already forgotten by the people who could have acted on them. That's changing for a few concrete reasons rather than as a general digitization trend. Building management systems and PLC-based equipment controls increasingly expose their status data through standard protocols like MQTT and OPC-UA, which means a CMMS can subscribe to a stop event the instant it happens rather than waiting for a technician to write it up. Mobile-first work order apps have also made guided reason-code entry fast enough that technicians actually use it under time pressure, instead of defaulting to a vague note they'll never expand on later. And as facility reliability programs mature, more teams are formally adopting structured RCA methods — 5-Why or fishbone analysis — as a required step before a high-impact work order can close, rather than an optional exercise reserved for major incidents. Together, these shifts mean the lag between an event happening and a report reflecting it has dropped from weeks to effectively real time on facilities that have made the switch — which is what actually makes root cause tracking usable day to day instead of a retrospective exercise nobody has time for.
Stop logging symptoms. Start finding the pattern underneath them.
Connect reason-coded downtime data to root cause tracking and corrective-action follow-up, all inside the CMMS your team already uses.
What a downtime report looks like before and after root cause discipline
- Downtime recorded as start time, end time, and a free-text note
- Micro-stops under five minutes routinely go unrecorded
- Reports show which assets failed, not why they failed
- Same failure mode repeats without anyone connecting the events
- Monthly report compiled manually from several spreadsheets
- Every stop tagged with a constrained, consistent reason code
- Sensor or BMS integration captures stops automatically, including micro-stops
- Pareto view ranks the true bad actors by cumulative downtime hours
- Repeat failures trigger a structured RCA before the ticket closes
- Live dashboard replaces manual report assembly entirely
Downtime data needs a different view at each level of the organization
A single downtime dashboard rarely serves everyone well. What a shift supervisor needs to act on differs from what a facility director needs to plan around.
Shift Level
A live view of open stops and the current top failure reason, so the technician on shift reacts within the hour, not next week.
Facility Level
A rolled-up Pareto ranking assets by downtime hours, giving the facility manager one screen to prioritize the next PM budget cycle.
Portfolio Level
A cross-site scorecard comparing reliability trends building to building, turning scattered site reports into one benchmark leadership can act on.
Building all three views from the same underlying reason-code data, rather than three separate reporting processes, is what keeps them consistent. When a facility manager's Pareto and a portfolio director's scorecard are pulling from different data sets, the numbers rarely agree, and the report loses credibility exactly when leadership starts paying attention to it.
What to confirm before turning on automated downtime reporting
Switching from manual logs to structured, automated downtime reporting works best when a few foundations are in place first. Teams that skip straight to dashboards without these often end up with clean-looking reports built on inconsistent underlying data.
A reason-code taxonomy is agreed and documented before technicians are asked to use it, not built ad hoc as entries come in.
Every critical asset is represented in the CMMS with an accurate record, so events route to the right place automatically.
A threshold is set for which events require a full RCA versus a quick reason-code tag only.
Reporting views are built for each audience — shift, facility, and portfolio — rather than one dashboard for everyone.
A review cadence is set so Pareto rankings actually get looked at monthly, not generated and ignored.
Where downtime reporting programs quietly stall
The technology rarely causes a downtime reporting program to fail. The process built around it usually does, and the same handful of gaps show up across facility teams regardless of industry.
Too many reason codes at launch
A list of two hundred codes looks thorough on paper but overwhelms technicians in the field, who default back to the vaguest option available.
RCA treated as optional
Without an enforced trigger, structured root cause analysis quietly becomes something only major incidents get, while the repeat minor failures never receive one.
Nobody owns the Pareto review
A ranked report that no one is accountable for reviewing monthly tends to sit unopened, no matter how accurate the underlying data is.
Common questions on facility downtime reporting
What's the difference between a downtime log and a root cause report?
A log records that an asset stopped and restarted. A root cause report traces why it stopped and links that cause to a corrective action tracked to closure.
Do we need sensors to get useful downtime reporting?
No. Guided technician entry with a constrained reason-code list improves data quality significantly on its own; sensor integration adds automatic capture on top of that.
How many reason codes should a facility start with?
Most teams start with a three-level tree of roughly fifteen to thirty codes — broad enough to avoid "miscellaneous," specific enough to stay usable at entry time.
How does root cause tracking connect to a CMMS work order?
When a downtime event closes, the root cause and corrective action are attached to the same work order record, so the fix stays linked to the event that caused it. Book a Demo to see it live.
Can old downtime data be retroactively coded?
Yes, though most teams find it more effective to start disciplined capture going forward and build the Pareto view as new, cleanly coded data accumulates.
Turn your downtime log into a findable pattern
Structured reason codes, Pareto reporting, and root cause tracking that ties every stop back to the asset, the cause, and the fix.
Free trial · No credit card