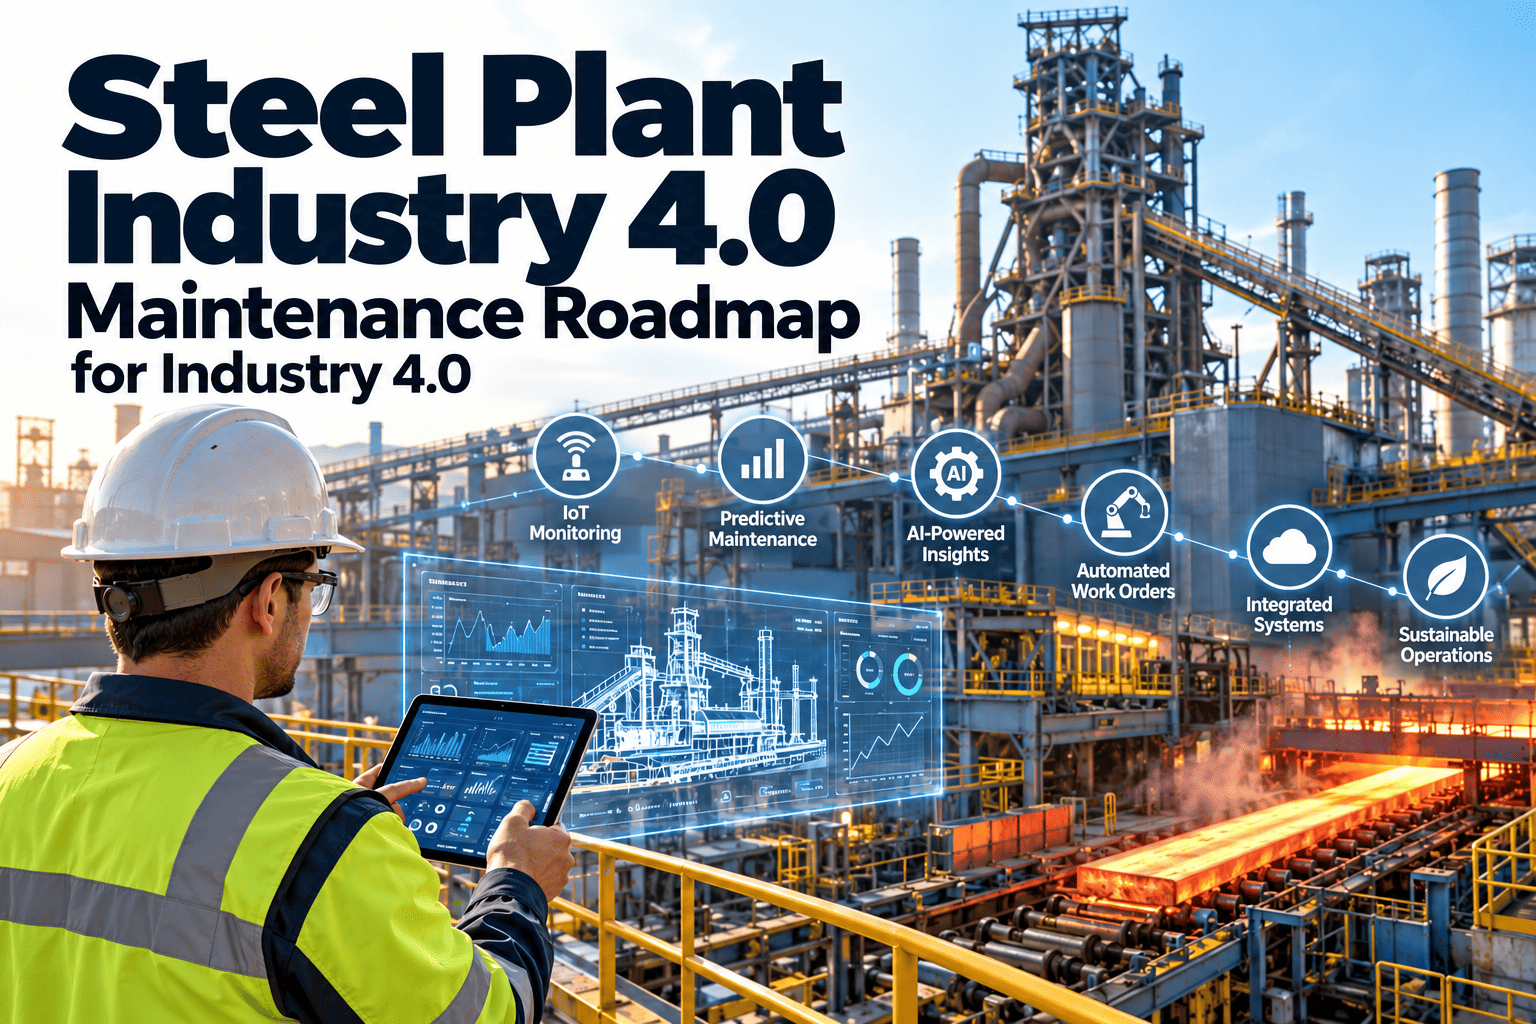
Most steel plants already own the ingredients of an Industry 4.0 maintenance program: sensors on critical drives, a historian full of trends, and technicians who know which assets cause trouble. What they often lack is a sequence that turns those pieces into decisions. This roadmap describes how a steel plant can move from paper and reactive repairs toward condition-based and predictive work, step by step, using Oxmaint maintenance management software as the system where asset data, work orders and results meet.
Steel Plant Industry 4.0 Maintenance Roadmap for Industry 4.0
Modernise maintenance in stages that pay for themselves: clean asset data first, then digital work, then condition signals, then prediction. Each stage proves value before the next begins.
Why steel plants struggle to turn digital ideas into maintenance results
Harsh, continuous operations
Heat, dust, scale and vibration damage instruments, and long campaigns leave few windows for installation or repair.
Mixed generations of equipment
Modern drives sit beside decades-old gearboxes and controllers, so no single connection method covers the plant.
Data without context
Historians hold millions of tags, but few are linked to a named asset, a failure mode or a work order.
Pilot fatigue
Isolated pilots show promise, then stall because nobody owns the process of acting on the alerts.
The common thread is that technology arrives faster than the maintenance process that should use it. A roadmap fixes the order of work so each investment has a place to land.
The five maintenance strategies and where steel plants sit
Industry 4.0 does not replace earlier strategies. It adds layers on top of them, and a healthy plant uses all five depending on asset criticality.
| Strategy | Trigger for work | Typical steel plant use | Data needed |
|---|---|---|---|
| Reactive | Failure has occurred | Low-criticality, easily replaced items | Failure and repair records |
| Preventive | Calendar or running hours | Lubrication, inspections, routine overhauls | Schedules and completion history |
| Condition-based | Measured condition crosses a limit | Bearings, gearboxes, fans, pumps, motors | Vibration, temperature, current, oil data |
| Predictive | Trend suggests future failure | High-consequence rotating and electrical assets | Long trend history linked to failures |
| Prescriptive | System recommends the best action | Mature programs across critical units | Trends, costs, spares and production context |
A practical rule
Do not skip rungs. Predictive models trained on sparse, inconsistent work order data produce alerts that technicians learn to ignore.
The technology stack behind a connected maintenance program
Think of the program as layers, each with a clear job. Problems usually appear where one layer hands data to the next.
Condition monitoring and process models can predict future equipment state, but the maintenance layer is where that prediction becomes a scheduled, assigned and verified job.
Stage one and two: build the foundation first
Digitise records
- Build the asset hierarchy from plant to unit to equipment to component.
- Assign criticality ratings with operations and production input.
- Load manuals, drawings and spare part lists against each asset.
- Replace paper work requests with digital ones from any device.
Standardise work
- Create preventive maintenance templates with defined steps and checklists.
- Introduce failure and cause codes so repeat problems become visible.
- Set priorities and response targets for emergency, urgent and routine work.
- Track backlog, planned work share and schedule compliance weekly.
These stages look unglamorous, but they decide whether later analytics work. Prediction needs a reliable record of what failed, when it failed and what was done about it.
Start the roadmap on a single critical unit
Build the asset hierarchy, digital work orders and inspection routes for one area, then see what the data teaches you before scaling out.
Choosing where to start: a criticality and data readiness matrix
Not every asset deserves sensors. Rank equipment by consequence of failure and by how much usable data already exists.
High consequence, good data
Start here. Connect existing signals to work orders and agree alert limits with the operators.
High consequence, little data
Invest in sensors or manual readings, because the cost of a failure justifies measurement.
Lower consequence, good data
Use simple thresholds and let the system raise routine work orders without extra analysis.
Lower consequence, little data
Keep preventive or run-to-failure strategies. Do not spend digital budget here yet.
Stage three and four: from condition signals to prediction
The feedback step is the one most programs omit. When technicians record what they found, the plant learns which alerts were real and which were noise.
- Begin with fixed alert limits agreed with reliability engineers before trying advanced models.
- Review every alert for the first months and record whether the inspection confirmed a fault.
- Reduce false alarms before adding new signals, because trust is hard to rebuild.
- Where a digital twin or process model exists, feed its findings to maintenance as planned work.
An eighteen month view of the roadmap
Foundation
- Asset hierarchy and criticality for the pilot unit
- Digital work requests and orders
- Mobile inspection routes
Standardisation
- Preventive templates and failure codes
- Spare parts linked to assets
- Weekly KPI review
Condition based work
- Selected signals feeding alerts
- Alert to work order rules
- Findings recorded after inspection
Prediction and scale
- Trend based failure warnings
- Rollout to further units
- Cost and reliability reporting
Common roadmap mistakes and their fixes
Condition monitoring techniques by steel plant asset
Different failure modes announce themselves through different signals. Matching technique to asset keeps monitoring budgets focused on what is actually detectable.
| Technique | Where it fits | What it can reveal | Record in the maintenance system |
|---|---|---|---|
| Vibration analysis | Fans, blowers, gearboxes, rolling mill drives, pumps | Imbalance, misalignment, bearing wear, looseness | Reading, alert level, inspection result |
| Thermography | Electrical cabinets, motors, transformers, refractory shells | Hot connections, overload, insulation loss | Image, temperature, corrective task |
| Oil analysis | Gearboxes, hydraulic power units, lubrication systems | Wear metals, contamination, degraded lubricant | Sample date, result, oil change order |
| Motor current analysis | Large motors and conveyor drives | Rotor faults, load changes, supply problems | Trend value and follow-up inspection |
| Ultrasound | Compressed air, steam, bearings, valves | Leaks, lubrication needs, early bearing damage | Leak tag, location, repair order |
| Visual and mobile rounds | All areas, especially hard-to-instrument equipment | Leaks, wear, noise, abnormal conditions | Checklist answers with photos |
What clean maintenance data looks like
Advanced analytics depends on boring details. Before investing in models, check the records against the following basics.
- Every asset has a unique identifier that matches its tag in the control system or historian.
- Work orders carry a failure code, a cause code and the component that failed.
- Start and finish times reflect real work, not end-of-shift guesses.
- Spare parts consumed are recorded against the asset and the job.
- Duplicate and obsolete assets are removed or flagged, so trends are not split across records.
Why this matters
A model that predicts bearing failure needs to know which bearing failed and when. If that history is missing or inconsistent, even good sensors cannot give trustworthy predictions.
People and change: the part technology does not solve
Technicians
- Involve them in designing checklists and failure codes.
- Keep mobile forms short, with pick lists instead of free text.
- Show how recorded findings changed a decision.
Planners and supervisors
- Use backlog and schedule views in the weekly planning meeting.
- Agree priority rules with operations, so urgent work is defined once.
- Review alert outcomes together with reliability engineers.
Management
- Set stage goals in terms of reliability and cost outcomes.
- Protect time for training and for data clean-up.
- Fund the next stage when the previous one shows results.
Building the business case without inventing numbers
Use your own plant history rather than generic benchmarks. A credible case compares the cost of the program with the cost of the events it should prevent or shorten.
- List the last two years of unplanned stoppages on the pilot unit, with duration and lost production.
- Add repair cost, emergency purchasing and overtime tied to those events.
- Estimate how many were detectable with the signals you plan to use.
- Include avoided inspections where condition-based tasks replace fixed-interval ones.
- Review the case after each stage using measured results, and adjust the plan.
Treat vendor claims and published averages as prompts for questions, not as numbers to copy into the budget.
KPIs to prove each stage is working
Trends shaping steel plant maintenance in 2026
- Plants are moving from isolated condition monitoring systems to shared platforms where alerts, work orders and results are visible together.
- Mobile devices are replacing clipboards on rounds, giving timestamped, attributed readings and photos.
- Remote monitoring and vendor support are growing, which raises the importance of clear data ownership and access control.
- Decarbonisation and reporting requirements are pulling energy and emissions data into the same conversation as reliability.
- Skilled labour is scarce, so digital work instructions and recorded history help newer technicians make good decisions.
Governance, security and integration questions to settle early
Industry 4.0 connects systems that were once separate, so agree the rules before connections are built.
- Decide which system is the master for asset data, so changes are made once and shared.
- Define which direction data may flow between plant networks and enterprise systems.
- Give each user role the access it needs and no more, with logs of who changed what.
- Document how alerts are routed, acknowledged and escalated if nobody responds.
- Plan for sensors and software that will be replaced, with data exports that keep history intact.
Operating model: who runs the roadmap
A roadmap needs a small, stable team rather than a committee that meets once a quarter. A reliability engineer owns the strategy and alert limits, a maintenance planner owns the schedule and backlog, and an operations representative owns access to equipment and shutdown windows. A sponsor from plant management removes obstacles and protects time for the work.
- Meet weekly during each stage, and monthly once the stage is stable.
- Keep a single list of decisions, owners and dates that everyone can see.
- Publish a short monthly summary of results to the wider plant, so progress is visible.
Signs your plant is ready for the next stage
- Work orders are created and closed digitally for most jobs on the pilot unit.
- Failure and cause codes are used consistently, and reports based on them are trusted.
- Technicians open the mobile checklists without being reminded.
- Planners can see backlog, schedule compliance and parts availability in one view.
- Operations and maintenance agree on criticality and on what counts as urgent.
What a pilot review should answer
Decision quality
Look for examples where a trend or alert changed the timing or scope of a job.
Alert trust
Check the confirmation rate and whether technicians acted on alerts without being chased.
Record completeness
Sample closed work orders for failure codes, parts used and honest time entries.
Scalability
Confirm templates, naming and training can be reused on the next unit without a new project team.
Where Oxmaint fits in the roadmap
- Asset management holds the hierarchy, criticality, documents and full maintenance history.
- Preventive maintenance and scheduling move routine work from paper to a visible calendar.
- Work orders and mobile workflows give technicians instructions, checklists and a place to record findings.
- Inspections capture readings and observations that feed condition-based decisions.
- Inventory links spare parts to assets, so planned jobs are not delayed by missing components.
- Reports and dashboards show backlog, compliance and reliability trends to managers and operations.
Integration with historians, SCADA, MES or ERP depends on your systems, so discuss your architecture during a demo before planning connections.
Roadmap questions steel teams ask
How long does an Industry 4.0 maintenance roadmap take?
Expect a pilot unit in months and wider scale in one to two years, depending on data quality and resources.
Do we need sensors on every asset?
No. Instrument assets whose failure is costly and where condition changes are detectable.
Can a CMMS support predictive maintenance?
It turns alerts into tracked work and records outcomes. You can book a demo to see the flow.
What should we digitise first?
Assets, work orders and inspections. You can sign up and begin with one unit.
Where does a digital twin fit?
It supports analysis of plant behaviour, while maintenance records confirm what actually happened.
Move your maintenance program up one rung this quarter
Replace guesswork with linked asset records, digital work and condition data, one unit at a time, and build a case for the next stage from real results.