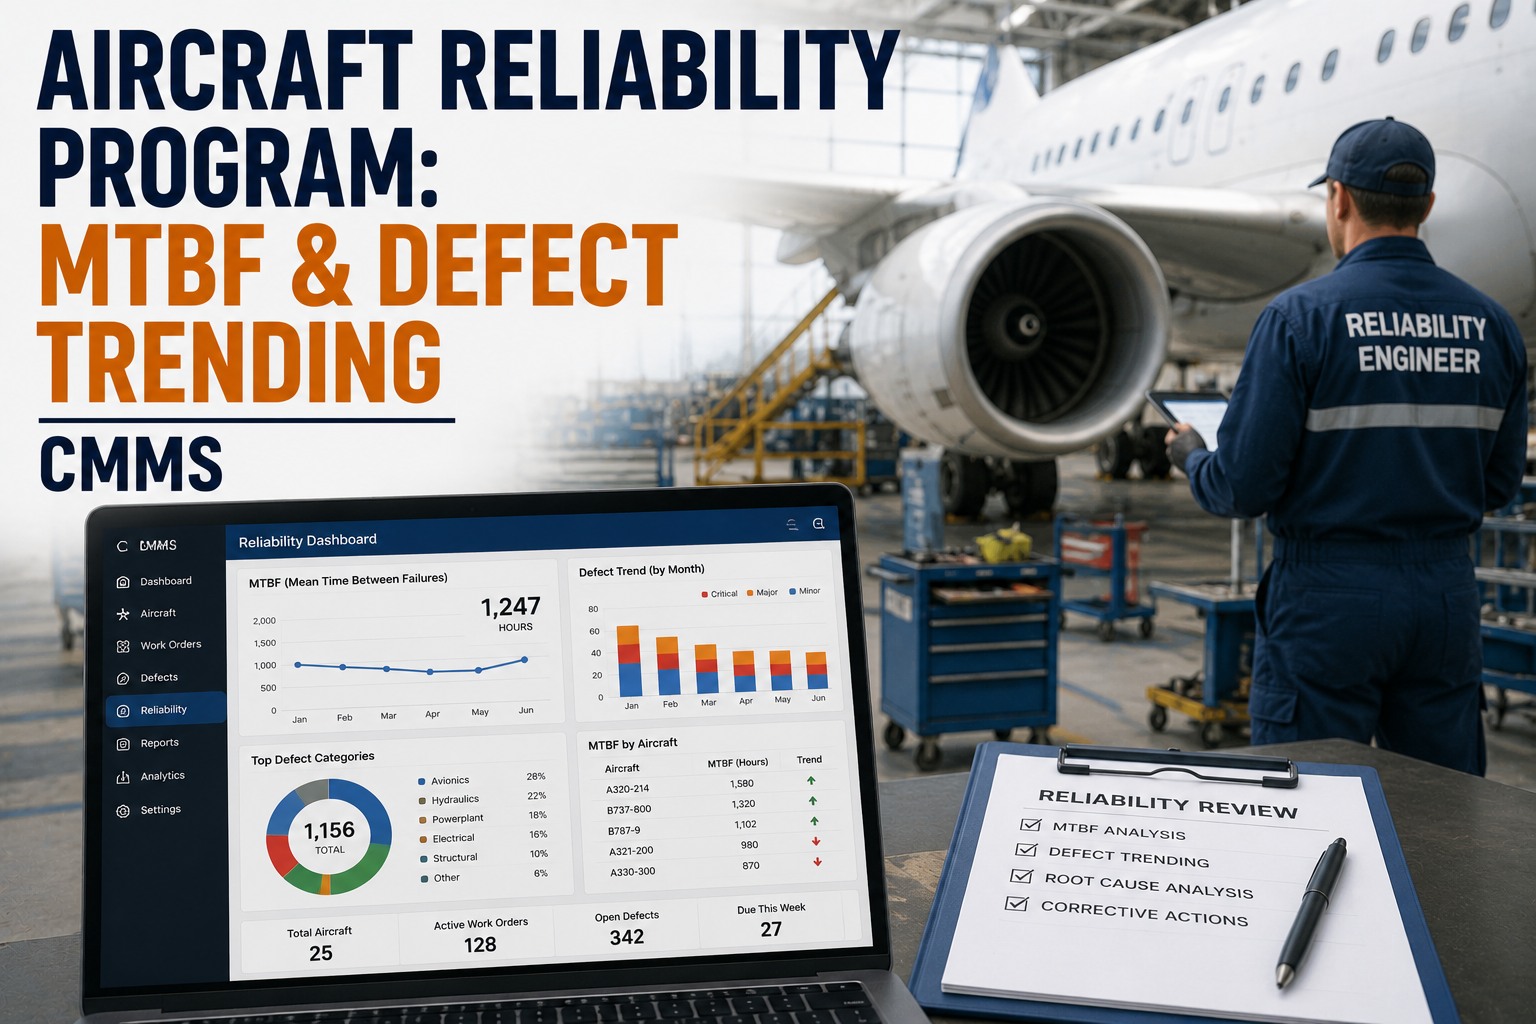
An aircraft reliability program is where airlines catch systemic component issues before they become fleet-wide AOG problems. This guide covers reliability program design in CMMS for aviation, including MTBF tracking by component and position, defect trend analysis, alert level triggers, corrective action loops, and how to align your reliability program with EASA Part-M and FAA CAMP expectations. Start Free Trial to operationalize these workflows inside a CMMS built for aviation maintenance teams.
Is a single recurring component quietly draining 12% of your available seat-kilometers?
For most regional fleets, two or three defect families generate the majority of unscheduled removals. A CMMS-driven reliability program flags those patterns weeks before they cascade into AOG events — turning scattered maintenance logs into a structured MTBF and defect-recurrence signal.
What a modern aircraft reliability program actually measures
A reliability program is not a log of past failures — it is a closed-loop monitoring system that converts component removal data, pilot reports, and shop findings into trended MTBF, alert thresholds, and corrective actions. EASA Part-M.510 and FAA CAMP (14 CFR Part 121.373) both expect operators to demonstrate that this loop is active, documented, and capable of driving task interval changes.
MTBF by component and position
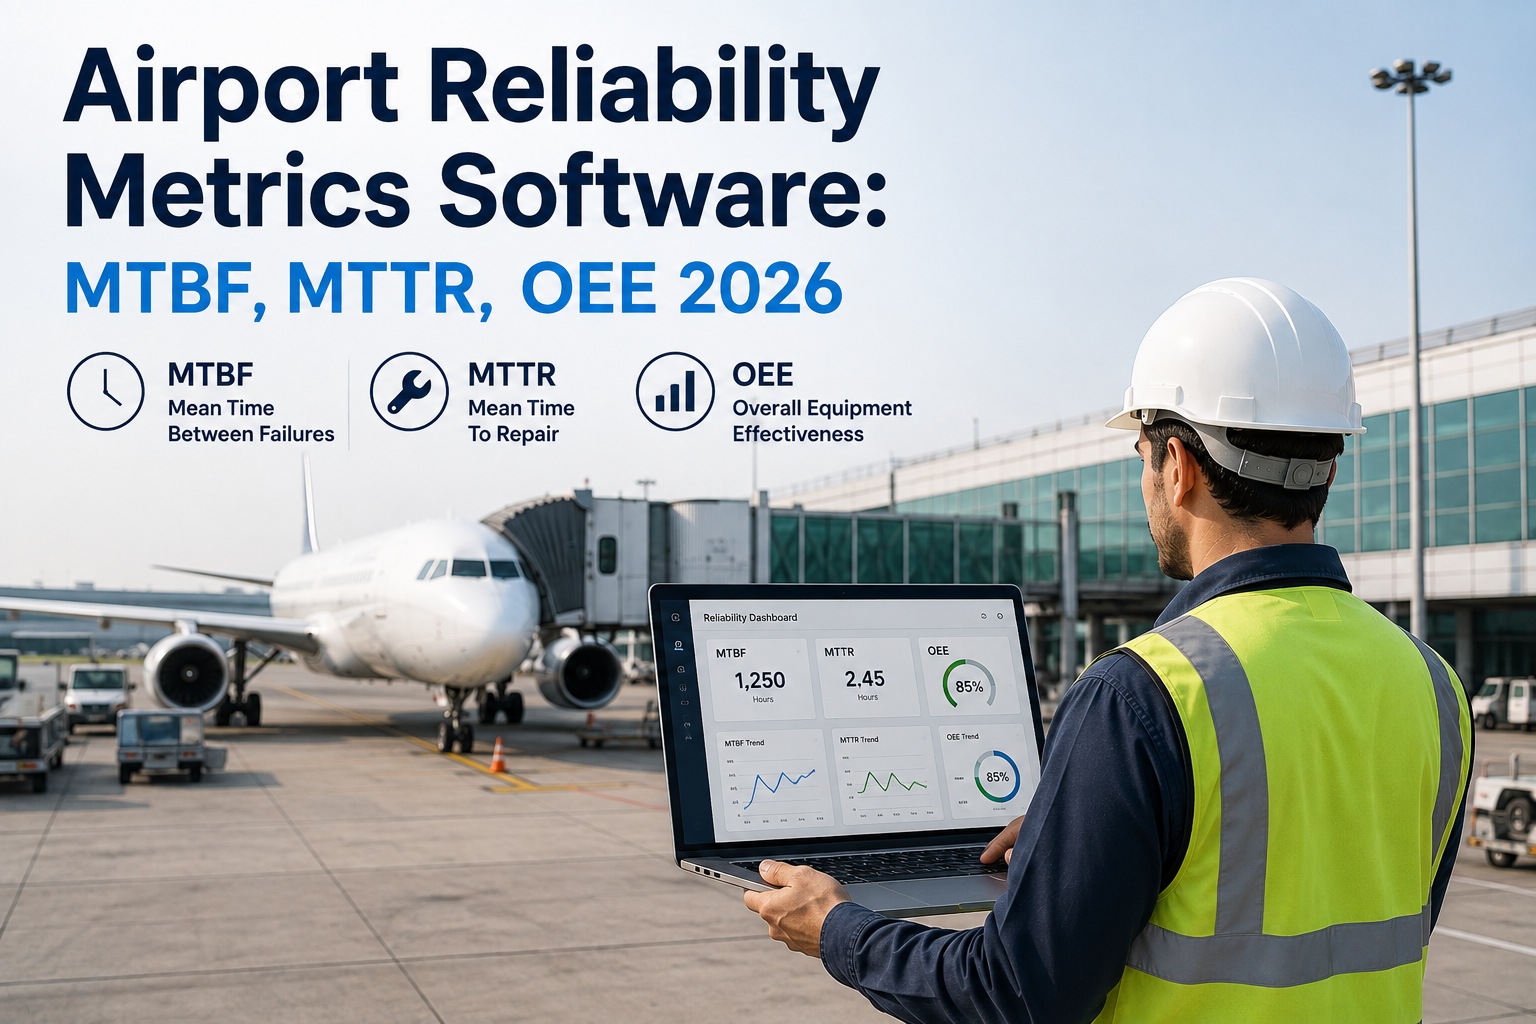
Mean Time Between Failures is calculated per part number, then sliced by aircraft registration and installation position (e.g., L/H pack vs R/H pack). Position-level MTBF exposes installation-environment failures that fleet averages hide.
Defect recurrence trending
Every defect code is tracked month-over-month. A recurrence index above 1.0 means the same defect is reappearing faster than the historical baseline — the earliest reliable signal that a corrective action is failing.
Alert level triggers
Upper control limits (UCL) set at 2-sigma above the rolling mean trigger yellow alerts; 3-sigma breaches trigger red. The CMMS must auto-escalate red alerts to the reliability board within 24 hours.
Corrective action loops
Each alert opens a tracked CAR (Corrective Action Request) with owner, due date, and effectiveness review. The loop only closes when MTBF returns below the UCL for two consecutive reporting periods.
The MTBF formula and how to compute it per component
MTBF is the backbone metric of any aviation reliability program. The calculation looks simple, but the data hygiene behind it — clean removal reasons, accurate flight-hour denominators, and correct position attribution — is what separates a audit-ready program from a spreadsheet exercise.
Example: A fleet accumulates 48,200 flight hours in a quarter. Pack P/N 7001-C has 9 unscheduled removals in the same window. MTBF = 48,200 ÷ 9 = 5,356 hours. If the prior 4-quarter rolling MTBF was 7,800 hours, the component has dropped 31% — well past a 25% alert threshold.
The lower control limit (LCL) is set two standard deviations below the 12-month rolling MTBF mean. A breach triggers a yellow alert in the CMMS. A drop below 3-sigma triggers a red alert and mandatory reliability board review within 24 hours per CAMP expectations.
| Component / P/N | Fleet FH (quarter) | Unsched. Removals | MTBF (hrs) | Prior MTBF | Δ % | Alert |
|---|---|---|---|---|---|---|
| ECU P/N 7001-C | 48,200 | 9 | 5,356 | 7,800 | −31% | Red |
| Pack P/N 2180-A | 48,200 | 6 | 8,033 | 9,100 | −12% | Yellow |
| FCU P/N 4450-B | 48,200 | 3 | 16,067 | 15,400 | +4% | Green |
| IDG P/N 9120-D | 48,200 | 11 | 4,382 | 6,200 | −29% | Red |
| Hyd Pump P/N 3300-K | 48,200 | 4 | 12,050 | 11,800 | +2% | Green |
Catching recurrence before it becomes an AOG
A 90-day rolling defect recurrence timeline is the most powerful early-warning tool in a reliability program. When the same ATA chapter defect code reappears on the same ship or position within three months, the CMMS should auto-flag it — long before the third recurrence turns into an AOG dispatch hit.
First defect logged
Bleed air valve ATC 36-11 reported on aircraft #2247. Squawk cleared, valve reset. No CMMS alert — single occurrence below UCL. Baseline recurrence index = 0.3.
Recurrence detected — yellow alert
Same defect code reappears on the same ship, same position within 28 days. Recurrence index jumps to 1.4. CMMS issues yellow alert and opens a monitoring ticket. Reliability engineer reviews shop findings.
Third recurrence — red alert, CAR opened
Third occurrence on ship #2247 plus first occurrence on sister ship #2251. Recurrence index = 2.7, exceeds 3-sigma UCL. Red alert auto-escalated to reliability board. Corrective Action Request opened with 30-day due date.
Corrective action verified — loop closed
SB 36-1147 incorporated fleet-wide. MTBF climbs from 5,356 hrs back to 7,920 hrs across two consecutive reporting periods. CAR closed with effectiveness confirmation. Reliability program audit-ready.
Configuring reliability alerts that actually drive action
The difference between a reliability program and a maintenance log is automation. A CMMS configured for aviation reliability must calculate, compare, and escalate without manual spreadsheet work. Here is the exact configuration checklist reliability engineers use to keep alert fatigue low and audit readiness high.
Data aggregation
- Auto-aggregate unscheduled removals by P/N, S/N, ship, and position
- Pull flight-hour denominators from the flight ops feed every 24 hours
- Tag each removal with ATA chapter, defect code, and shop finding
Threshold setup
- Set 12-month rolling mean as baseline MTBF per component
- Configure 2-sigma LCL for yellow, 3-sigma for red alerts
- Add a 25% relative drop trigger as a secondary safety net
Escalation rules
- Yellow alert → reliability engineer inbox within 48 hours
- Red alert → reliability board chair within 24 hours, auto-CAR
- Third recurrence on same ship → mandatory root-cause review
Audit trail
- Every alert, CAR, and closure logged with timestamp and owner
- Exportable EASA Part-M / FAA CAMP compliance report on demand
- Effectiveness review tied to two consecutive sub-UCL periods
Aligning with EASA Part-M and FAA CAMP expectations
Both EASA and FAA require operators to demonstrate an active, data-driven reliability program — not just a document. The CMMS must produce evidence that alerts were generated, reviewed, acted upon, and verified. Here is how the two frameworks compare and what your CMMS must capture for each.
| Requirement | EASA Part-M.510 | FAA CAMP (14 CFR 121.373) | CMMS Evidence |
|---|---|---|---|
| Reliability program approval | Submitted to competent authority; reviewed annually | Approved under ops specs; reviewed during CAMP audits | Versioned program doc, sign-off log |
| MTBF / removal tracking | Mandatory for MSG-3 driven task intervals | Mandatory for condition-monitored items | Component-level MTBF dashboard, exportable |
| Alert thresholds | Statistical control limits, documented | Alert levels with defined response times | Threshold config log, breach timestamps |
| Corrective action records | Closed loop with effectiveness check | CAR system with management review | CAR records, closure evidence, review sign-off |
| Reporting frequency | Monthly reliability report to authority on request | Monthly CAMP summary to management | Auto-generated monthly reliability report |
A 32-aircraft regional fleet that cut unscheduled removals by 27%
A regional operator flying 32 E175s was spending roughly $4.1M annually on unscheduled component removals, with bleed-air and IDG failures dominating the top 10. Within nine months of deploying a CMMS-based reliability program, the fleet reduced unscheduled removals by 27% and recovered an estimated $1.1M in spares and AOG costs.
The bleed-air valve family was our biggest blind spot. Once the CMMS flagged the third recurrence on ship 2247 and auto-opened a CAR, we had a root cause and a fleet-wide SB incorporated within six weeks. Without the reliability alert, we would have lost two more aircraft to AOG that quarter.
Turn scattered maintenance logs into a reliability signal
Deploy a CMMS that calculates MTBF by component and position, trends defect recurrence, and auto-escalates alerts to your reliability board — all aligned with EASA Part-M and FAA CAMP expectations.
Aircraft reliability program — frequently asked questions
What is MTBF in an aircraft reliability program?
MTBF (Mean Time Between Failures) is the total fleet flight hours divided by the number of unscheduled component removals in a reporting period. It is tracked per part number, per aircraft, and per installation position so that reliability engineers can isolate whether a failure is driven by the component itself, the operating environment, or a specific ship.
How does a CMMS support defect recurrence trending?
The CMMS aggregates every defect code by ATA chapter, ship, and position, then calculates a rolling recurrence index. When the index exceeds 1.0 — meaning the defect is reappearing faster than the historical baseline — the system issues a yellow alert. A third recurrence on the same ship within 90 days triggers a red alert and a mandatory root-cause review. To see this workflow live, Book a Demo.
What alert levels should a reliability program use?
Most aviation reliability programs use a two-tier statistical model: yellow alerts at 2-sigma below the rolling MTBF mean, and red alerts at 3-sigma. A secondary trigger — a 25% relative drop versus the prior period — catches components that are degrading fast but have not yet breached the statistical threshold. Red alerts should auto-escalate to the reliability board within 24 hours.
How do I align my reliability program with EASA Part-M and FAA CAMP?
Both frameworks expect a documented, closed-loop program: MTBF tracking, alert thresholds, corrective action records with effectiveness reviews, and monthly reporting. Your CMMS must produce audit-ready evidence — alert logs, CAR records, closure sign-offs, and a monthly reliability report — on demand. A Start Free Trial lets you configure these outputs against your existing program structure.
How quickly can a CMMS-based reliability program show ROI?
Operators typically see the first actionable alerts within 30–60 days of going live, once the CMMS has ingested 12 months of historical removal and flight-hour data. Measurable reductions in unscheduled removals usually appear within 6–9 months, with payback driven by fewer AOG events, lower spares consumption, and reduced man-hours on repeat defect troubleshooting.
Build a reliability program that catches failures before the fleet does
Configure MTBF tracking, defect recurrence trending, and automated alert escalation inside a CMMS built for aviation maintenance. Align with EASA Part-M and FAA CAMP from day one.
Free 14-day trial · No credit card