Cement kilns rarely fail without warning, yet many plants still learn about a problem when the shell glows, the main drive trips, or a preheater cyclone blocks. In 2026, tighter margins, variable alternative fuels, and thinner maintenance teams make every unplanned stop harder to absorb. This guide covers the kiln reliability challenges that matter most, the signals that predict them, and how a connected maintenance management platform turns condition data into planned work instead of emergency repairs.
Top Cement Kiln Reliability Challenges in 2026: Unplanned Downtime and Failure Prediction
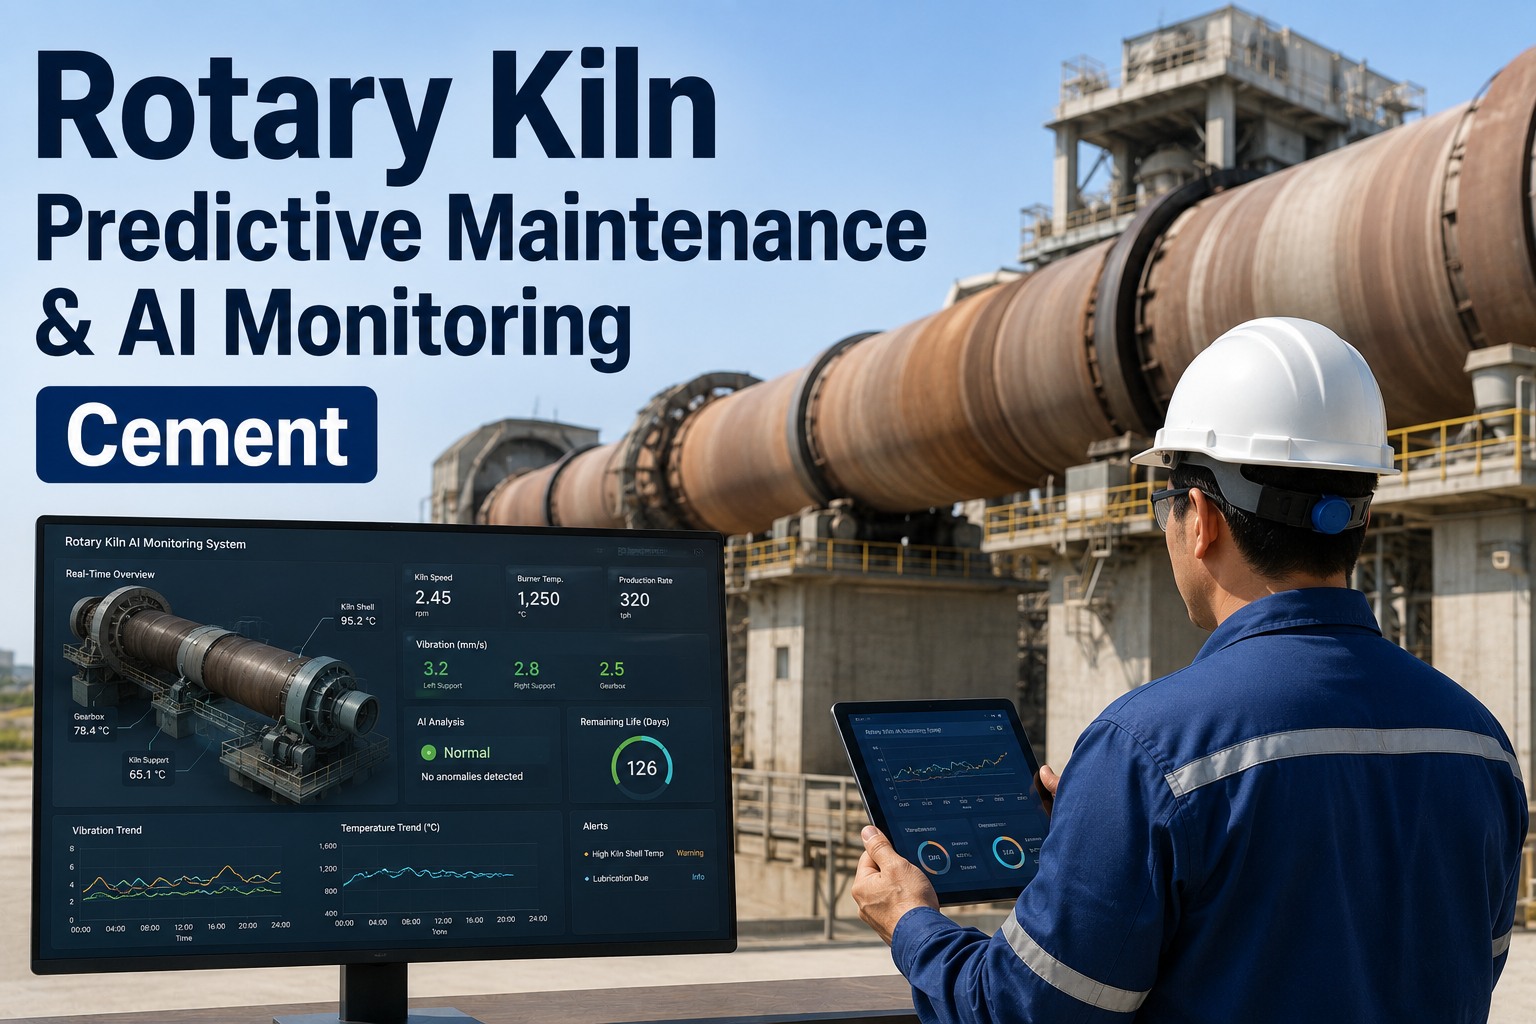
A rotary kiln is the single point of failure for the whole plant. When it stops unexpectedly, clinker output, fuel efficiency, refractory life and delivery commitments all take the hit. Oxmaint connects condition data, inspections and work orders so failures are predicted, planned and repaired inside the stop window.
Why unplanned kiln downtime is harder to absorb in 2026
Fuel variability
Higher alternative fuel use changes flame shape, coating behavior and gas chemistry. Chlorine, sulfur and alkali cycles speed up build-up and refractory stress, so equipment now sees conditions the original design never assumed.
Experience gap
Veteran kiln and maintenance staff are retiring, and what they know about shell color, drive sound and roller behavior is rarely written down. Without recorded baselines, newer technicians cannot separate normal drift from an early warning.
Cost and carbon pressure
Energy prices and carbon-related trade rules, such as the EU CBAM moving into its definitive phase in 2026, reward stable, efficient burning. Every unplanned stop and heat-up cycle wastes fuel and shortens refractory life.
What weak condition monitoring looks like on site
- Shell scanner alarms are acknowledged in the control room but never become a work order.
- Vibration, temperature and oil data sit in separate tools that nobody reviews together.
- Inspection rounds are recorded on paper and summarized weeks later, if at all.
- Preventive tasks follow the calendar instead of the actual condition of the equipment.
- Emergency repairs trigger rush purchases because critical spares were never linked to the asset.
- The same failure repeats because nobody recorded the cause or the corrective action.
Most plants already hold the signals they need
Better failure prediction rarely starts with new sensors. It starts with connecting information that already exists but sits in separate places.
- Shell scanner and thermography records for lining and shell condition.
- DCS trends for kiln drive current, back-end temperature, pressure drop and cooler pressures.
- Vibration route data for gearboxes, fans and motors.
- Oil analysis reports for kiln drive and cooler hydraulics.
- Shift logs and inspection notes describing unusual sounds, smells or leaks.
- Past work orders and failure reports showing where problems repeat.
Connect first, then extend
Linking these sources to the right asset gives planners a single timeline per component. Gaps in that timeline show exactly where additional sensors or inspections would add value.
Seven kiln reliability challenges to plan around
Refractory wear and shell hot spots
Lining loss in the burning and transition zones is the classic cause of forced kiln stops. Coating loss, flame impingement, thermal cycling and chemical attack thin the brick until shell temperature climbs, and late action can mean shell deformation rather than a simple brick patch.
Tyre, roller and shell condition
Tyre creep, roller wear, roller skew and shell ovality change how load is carried along the kiln. Small misalignment grows slowly, then appears as damaged retaining parts, roller surface defects or shell fatigue.
Kiln drive train
The girth gear, pinion, gearbox, coupling and main motor form a heavily loaded chain. Poor lubrication, shifting tooth contact and backlash changes damage gears long before a breakage, and replacement lead times are measured in months.
Preheater build-up and cyclone blockages
Circulating chlorides, sulfur and alkalis create sticky build-up in riser ducts and cyclone cones. Blockages force hazardous cleaning and often cut feed or stop the line entirely.
Clinker cooler reliability
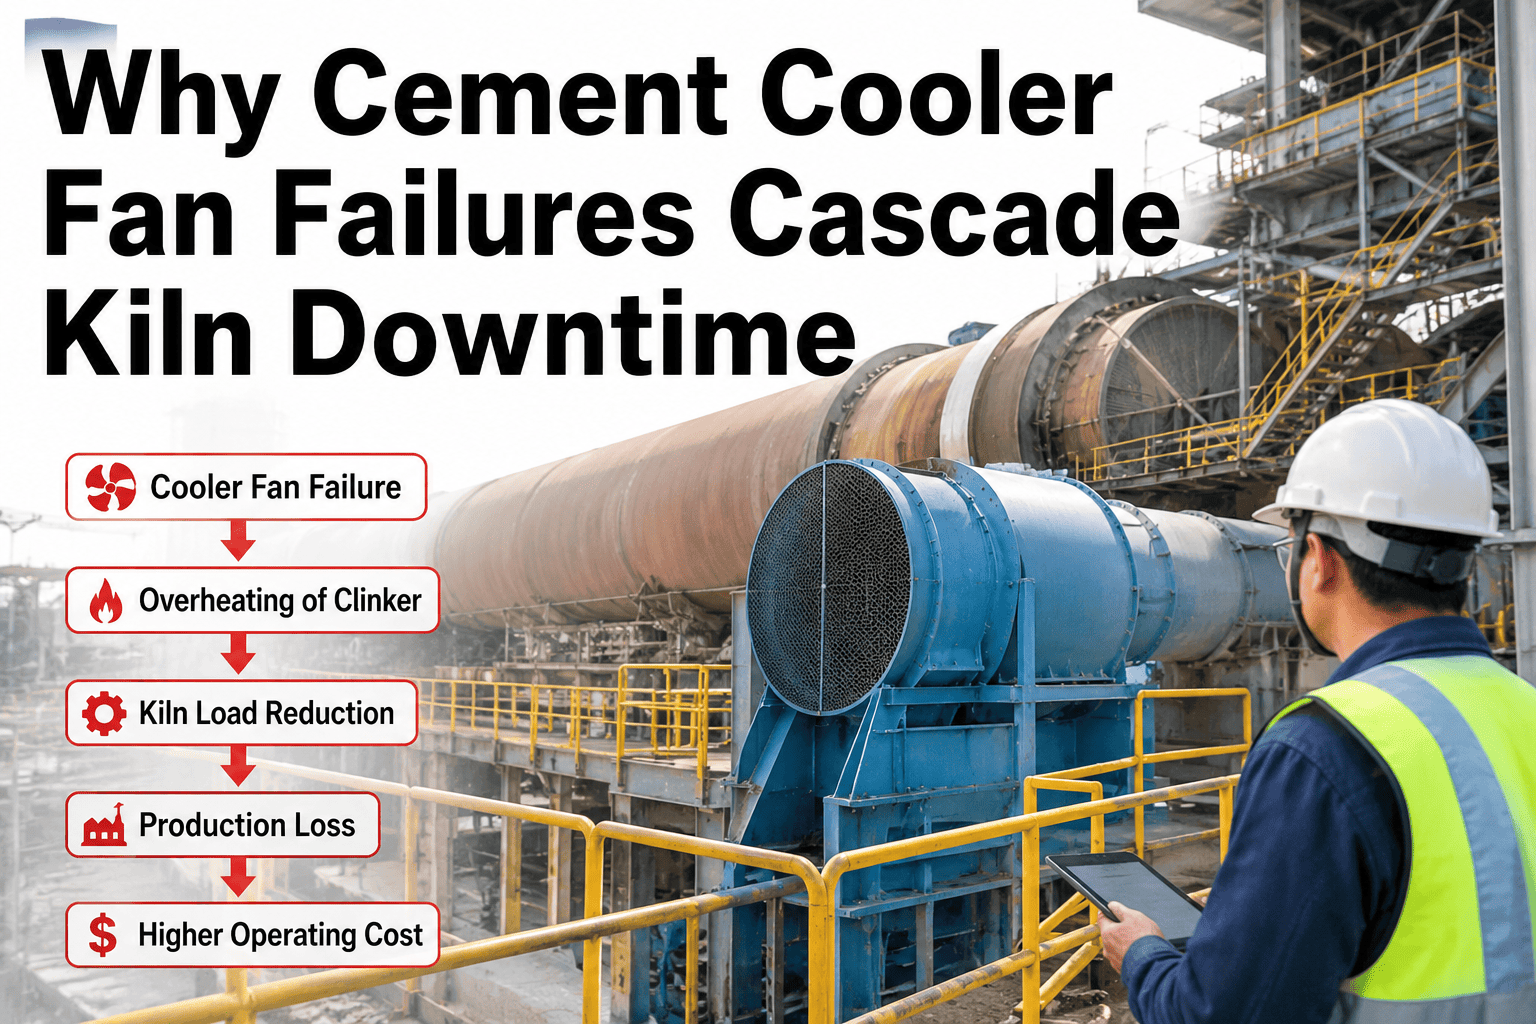
Grate plate wear, fan faults, hydraulic drive issues and uneven clinker bed distribution reduce heat recovery and raise clinker discharge temperature. That heat then stresses downstream conveyors and destabilizes the kiln.
Coating and ring instability
Rings and unstable coatings form when raw meal chemistry, fineness or fuel behavior shifts. They change kiln torque and gas flow, and a sudden ring collapse creates severe process upsets that stress every downstream asset.
ID fan, seals and auxiliary rotating equipment
The kiln can only run as long as its ID fan, inlet and outlet seals, and feed and fuel systems do. These supporting assets are often under-monitored because they look secondary, yet they trip the kiln just as effectively.
Kiln failure risk matrix: where to focus monitoring first
This illustrative matrix ranks failure modes by likelihood and consequence. Recalibrate it with your own failure history, because a plant with a new drive and an old cooler will place items differently.
How to use the matrix
- Start continuous or frequent monitoring in the red cells, where a miss is both likely and costly.
- Put amber cells on condition-based inspection routes with clear alert limits.
- Keep soft cells on simple time-based preventive maintenance and review them yearly.
Reactive kiln maintenance vs. predictive kiln maintenance
Reactive pattern
- Hot spots are patched after the shell has already discolored.
- Gearbox oil is sampled when someone remembers.
- Spare parts are ordered after the failure is found.
- Shift notes are the only record of abnormal behavior.
- Repair windows are dictated by the breakdown.
- Root causes are debated, not documented.
Predictive pattern
- Shell temperature trends trigger an inspection before brick loss spreads.
- Oil, vibration and current readings are trended per asset.
- Critical spares are linked to the asset and reserved in advance.
- Every abnormal reading becomes a traceable work order.
- Repairs are scheduled into planned stops.
- Failure codes and causes build a usable history.
Why kiln emergency repairs keep happening
Emergency repairs are rarely caused by a single missed inspection. They usually trace back to a handful of process gaps that repeat from one campaign to the next.
| Underlying cause | What it looks like on site | Practical fix |
|---|---|---|
| No condition baseline | Alarms have no context, and nobody is sure what normal looks like | Record baseline readings per asset and per campaign |
| Calendar-only preventive maintenance | Tasks are completed on time, yet failures still occur between them | Add condition-based triggers next to fixed intervals |
| Late parts planning | Emergency purchases and long waits for critical components | Link critical spares to assets and review lead times |
| Findings that are never closed | Inspection notes sit in a notebook and never reach a work order | Raise work orders directly from failed inspection items |
| Lost knowledge | The same fault is diagnosed from scratch each time it appears | Store failure codes, causes and photos in asset history |
Fix the process, then the equipment
Replacing a worn part solves one failure. Closing the process gap that let the wear go unnoticed prevents the next several.
From early signal to planned repair in five steps
1. Detect
A trend leaves its baseline: shell temperature, vibration, current or pressure drop.
2. Verify
A technician confirms the reading with a mobile inspection, photo or thermography check.
3. Plan
A work order is created with the task, parts, permits and estimated duration.
4. Execute
The repair happens in the next planned stop, with checklists and sign-off recorded.
5. Learn
Findings feed alert limits, PM intervals and spare parts decisions for the next campaign.
Kiln condition monitoring map for a cement plant
| Equipment | What to track | Typical method | Oxmaint workflow |
|---|---|---|---|
| Shell and refractory | Surface temperature, hot spot size | Shell scanner, thermography | Threshold alert to inspection work order |
| Tyres and rollers | Creep, gap, roller temperature | Creep sensors, manual readings | Scheduled readings with trend history |
| Girth gear and pinion | Contact pattern, backlash, lubrication | Visual inspection, vibration | Lubrication PM and inspection checklist |
| Gearbox and main motor | Vibration, oil condition, current | Vibration route, oil sampling | Condition-based task with parts link |
| Preheater cyclones | Pressure drop, stage temperature | DCS trends, round checks | Round checklist and cleaning work order |
| Cooler | Undergrate pressure, hydraulic pressure | DCS trends, visual checks | Grate plate inspection and spares tracking |
| ID fan | Bearing vibration and temperature | Online sensors, handheld route | Alert to corrective work order |
Plan the next kiln stop from condition data, not surprises
Start organizing kiln assets, inspections and work orders in one system, or walk through a cement-specific setup with our team.
Make every planned kiln stop count
A planned stop is the cheapest time to fix what condition monitoring found. Preparation decides whether the window is used for planned repairs or lost to surprises.
Before the stop
- Confirm scope from open inspection findings and trends.
- Stage refractory, gearbox parts, roller components and grate plates.
- Book contractors, cranes and scaffolding early.
- Prepare confined space, hot work and lockout permits.
During the stop
- Record as-found measurements such as brick thickness, tyre gap and gear contact.
- Update work orders as tasks finish, not at the end of the shift.
- Log extra findings so they enter the backlog.
- Keep safety verification steps documented.
After the stop
- Capture as-left values as the new baseline.
- Close out work orders with causes and part usage.
- Adjust PM intervals and alert limits using what was found.
- Hold a short review of what surprised the team.
Planned kiln work is also safer work
Emergency repairs push people into the hardest jobs under the most pressure. Predicting failures gives the team time to prepare properly.
- Preheater blockage clearing is hazardous, so fewer blockages mean less exposure.
- Hot kiln entry and confined space work need permits, gas checks and rescue plans that rushed jobs tend to shortcut.
- Planned lockout and isolation are easier to verify than breakdown isolation at night.
- Staged parts and scaffolding cut the time people spend in high-risk areas.
Reliability KPIs that show whether kiln downtime is falling
Unplanned stop frequency
Count kiln stops per campaign by cause. A falling count with a stable cause mix suggests the right fixes.
MTBF by asset group
Mean time between failures for drives, fans and cooler equipment shows where reliability is really improving.
MTTR
Mean time to repair reflects planning quality, spare availability and permit readiness, not only technician skill.
Emergency work share
The percentage of work orders raised as breakdowns. Lower is better, and the trend matters more than the number.
Schedule compliance
Planned tasks completed on time in stop windows. Poor compliance often explains repeat failures.
Repeat failure rate
Failures recurring on the same asset with the same cause point to weak root cause work or incomplete repairs.
How Oxmaint supports kiln reliability and failure prediction
Asset management
Structure the kiln line from preheater to cooler, down to gearboxes, rollers and fans, with full maintenance history per asset.
Preventive maintenance
Schedule lubrication, alignment checks and inspections by calendar, running hours or condition, and adjust as data accumulates.
Mobile inspections
Capture shell temperature notes, photos and round findings on the tower or kiln deck, so problems reach planners the same day.
Work orders
Turn alerts and inspection failures into assigned corrective work with priority, parts and completion records.
Inventory
Link critical spares, such as refractory, gearbox components and grate plates, to assets and reorder points.
Reporting
Track MTBF, MTTR, backlog and repeat failures on dashboards that engineering and plant management can both use.
A practical 90-day start on kiln failure prediction
Days 1 to 30
- Build the kiln asset hierarchy.
- Load the last two years of failure notes.
- Rank assets with the risk matrix.
Days 31 to 60
- Digitize kiln and preheater rounds.
- Set alert limits for the red-cell assets.
- Link critical spares to assets.
Days 61 to 90
- Convert alerts to work orders.
- Review emergency work share.
- Plan the next stop from the backlog.
Cement kiln reliability: frequently asked questions
What causes most unplanned cement kiln stops?
Refractory and shell issues, preheater blockages, drive problems and cooler faults lead the list. Your own failure history should set the exact priorities.
How can kiln failures be predicted?
Trend shell temperature, vibration, current, oil condition and pressure drop against baselines, then act on deviations. Set up assets and alerts to link each deviation to a work order.
Do we need new sensors to start?
Not always. Start with existing DCS trends, shell scanner data and inspection rounds, and add sensors where the risk matrix shows blind spots.
How does a CMMS reduce emergency repairs?
It links findings to planned work, spares and history, so problems are fixed in stop windows. You can book a demo to see this on a kiln asset tree.
Which KPIs should we track first?
Begin with unplanned stop frequency, emergency work share and schedule compliance. Add MTBF and MTTR once failure codes are consistent.
Move your kiln from emergency repairs to predictable reliability
Bring kiln inspections, condition data, spares and work orders into one platform and give your team a clear view of what needs attention before the next stop.