Six months ago, a 310-bed regional hospital's facilities and biomedical teams were running two separate backlogs, both sorted by date created, both routinely burying the tickets that mattered most behind the tickets that arrived first. A recurring OR HVAC fault sat unresolved for eleven days because three lower-priority requests happened to be logged ahead of it. This is the story of how that hospital moved from a flat, date-ordered queue to an AI-prioritized work order system, and what changed in the ninety days that followed — not a hypothetical, but the actual before-and-after a facilities director tracked week by week.
From an 11-Day-Old HVAC Fault to a Same-Shift Fix
The facilities team logged every request in date order and worked top-down. There was no scoring model to distinguish a squeaky cart wheel from an OR HVAC fault — both were "open tickets," and both waited their turn. A recurring OR-4 HVAC temperature fault, logged between two lower-urgency requests, sat unresolved for eleven days before a surgeon flagged it directly to administration. The backlog itself was not shrinking; new tickets arrived faster than the flat queue could clear them, and nobody could say with confidence which ten tickets in the 340 open actually mattered most.
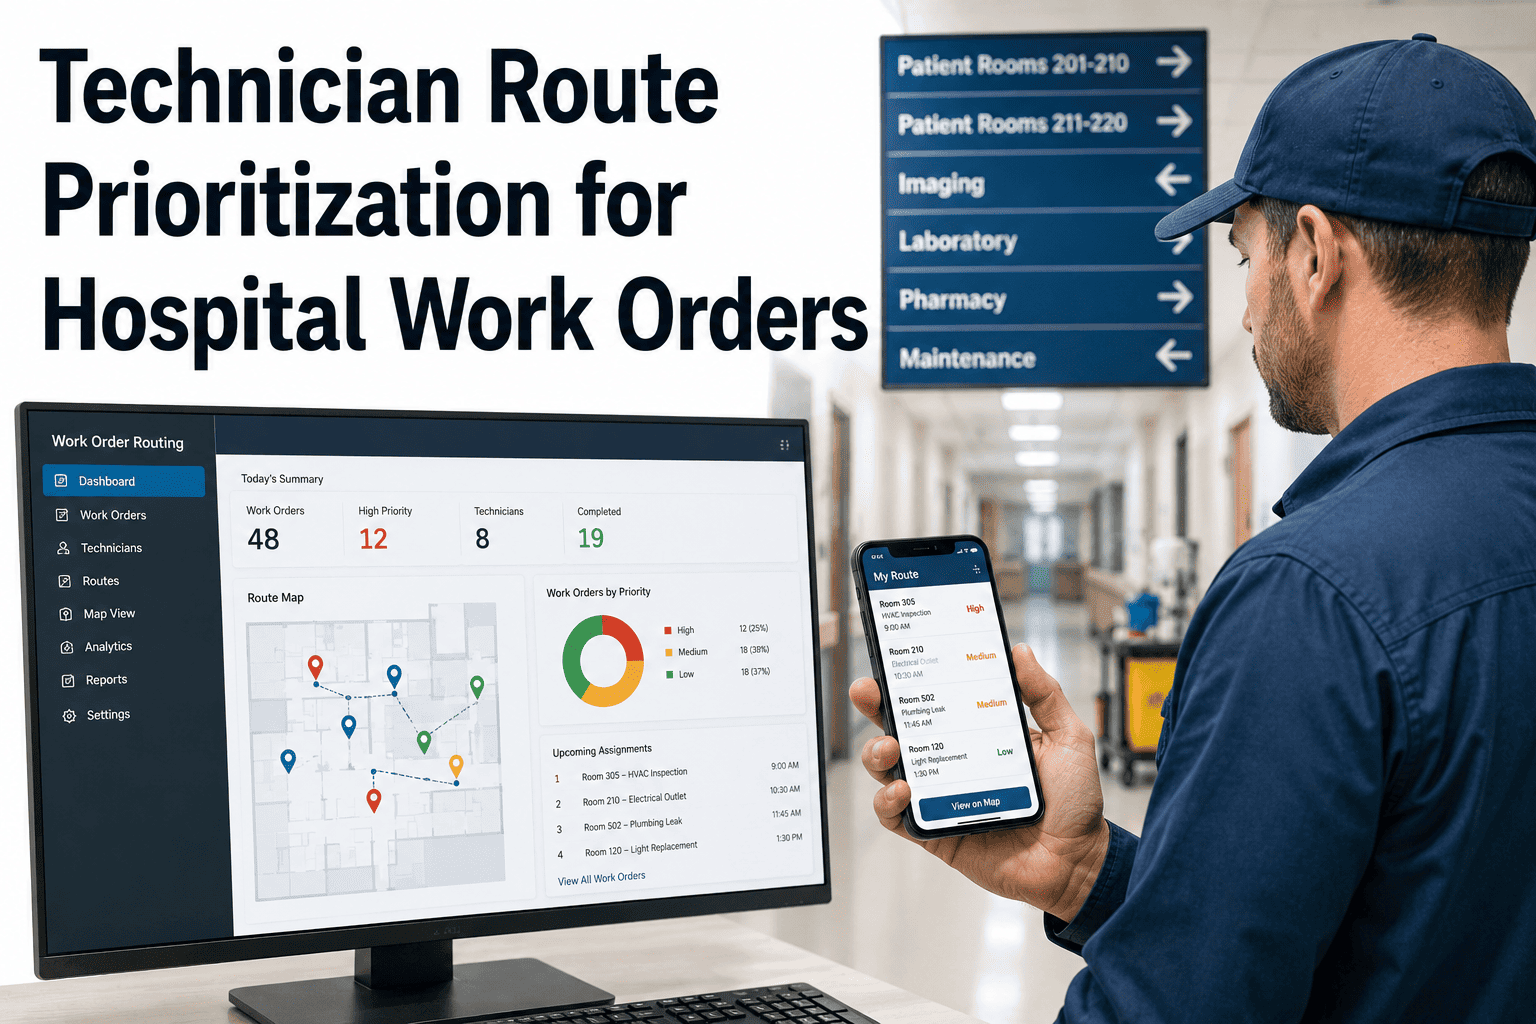
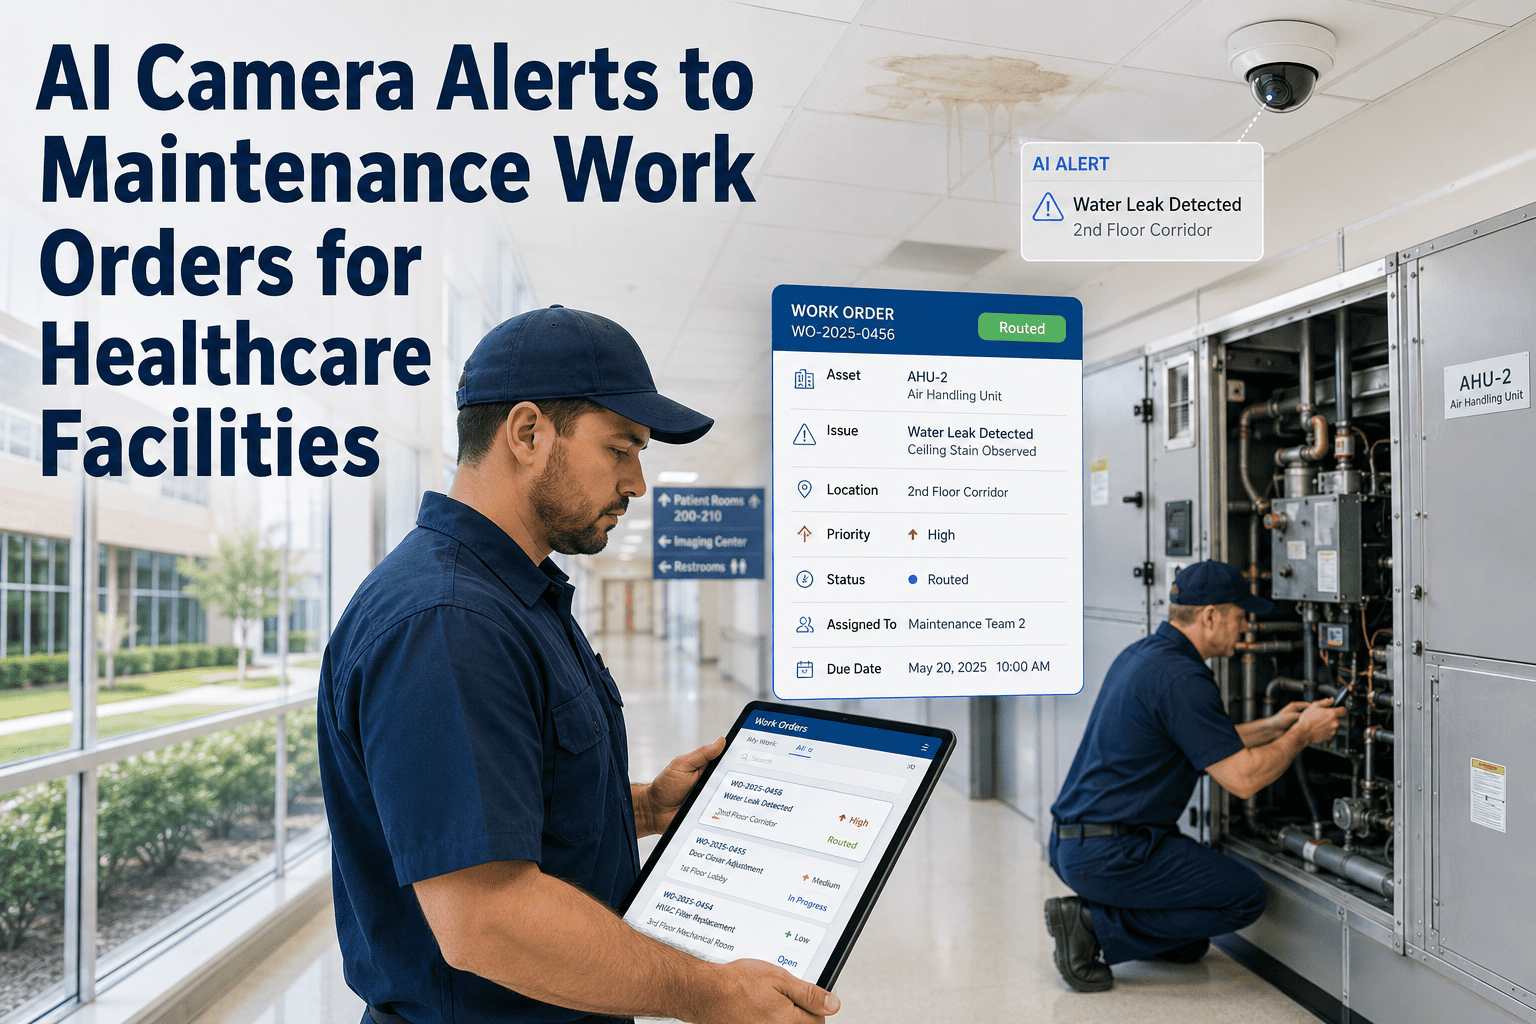
The hospital deployed Oxmaint's AI backlog prioritization engine across both facilities and biomedical queues over a phased eight-week rollout. Every open ticket was scored on patient impact, asset criticality, compliance deadline proximity, and failure-probability trend, with technician availability layered in for dispatch. The OR HVAC asset was tagged at the highest criticality tier during onboarding — meaning the next fault on that same unit would surface at the top of the queue automatically, not wait for someone to notice a pattern.
The Results — 90 Days Before and After
See What Your Own Backlog Looks Like Scored the Same Way.
This result came from re-ranking an existing ticket list, not replacing it. Bring your current backlog to a call and see it scored live.
The 90-Day Rollout Timeline
What the Facilities Director Said
The number that convinced our administration was not the average — it was the outlier. Before this, an eleven-day-old HVAC fault on an OR could sit invisible in a list of 340 tickets, because nothing in the system said it was different from a broken vending machine. Now that same fault type would surface at the top of the queue the moment it re-occurs, because the asset itself carries the criticality tag, not the memory of whoever logged the last ticket. We did not add headcount to get these numbers. We changed the order the same headcount worked in.
Frequently Asked Questions
Did the hospital need to replace its existing CMMS to run this rollout?
No — the facility migrated its full work order and asset history onto Oxmaint as part of the eight-week rollout, running the old system in parallel until the cutover was confirmed stable. Book a demo to discuss a migration path from your current system.
How was the OR HVAC asset re-tagged so the next fault would surface immediately?
During onboarding, the facilities team walked the asset registry and manually flagged life-support-adjacent and OR-critical infrastructure at the highest tier — a one-time tagging exercise that then applies automatically to every future ticket against that asset. No re-tagging is needed per ticket.
Why did PM displacement drop so significantly during the rollout?
Once reactive tickets were correctly risk-ranked instead of uniformly urgent, technicians stopped defaulting to "whatever's newest" and PM work no longer lost every scheduling conflict by default. See the full mechanics of the scoring model.
Is this result typical, or specific to this hospital's ticket volume?
The magnitude varies with starting backlog size and asset mix, but the direction of change — critical ticket age dropping and PM displacement falling — is consistent across facilities that move from date-order to risk-order queues. Start a free trial to see your own backlog re-ranked.
Your Backlog Has Its Own Eleven-Day HVAC Fault Buried in It Somewhere.
The only way to find it is to re-score the queue. Oxmaint's team will do that with your real ticket list on the call.