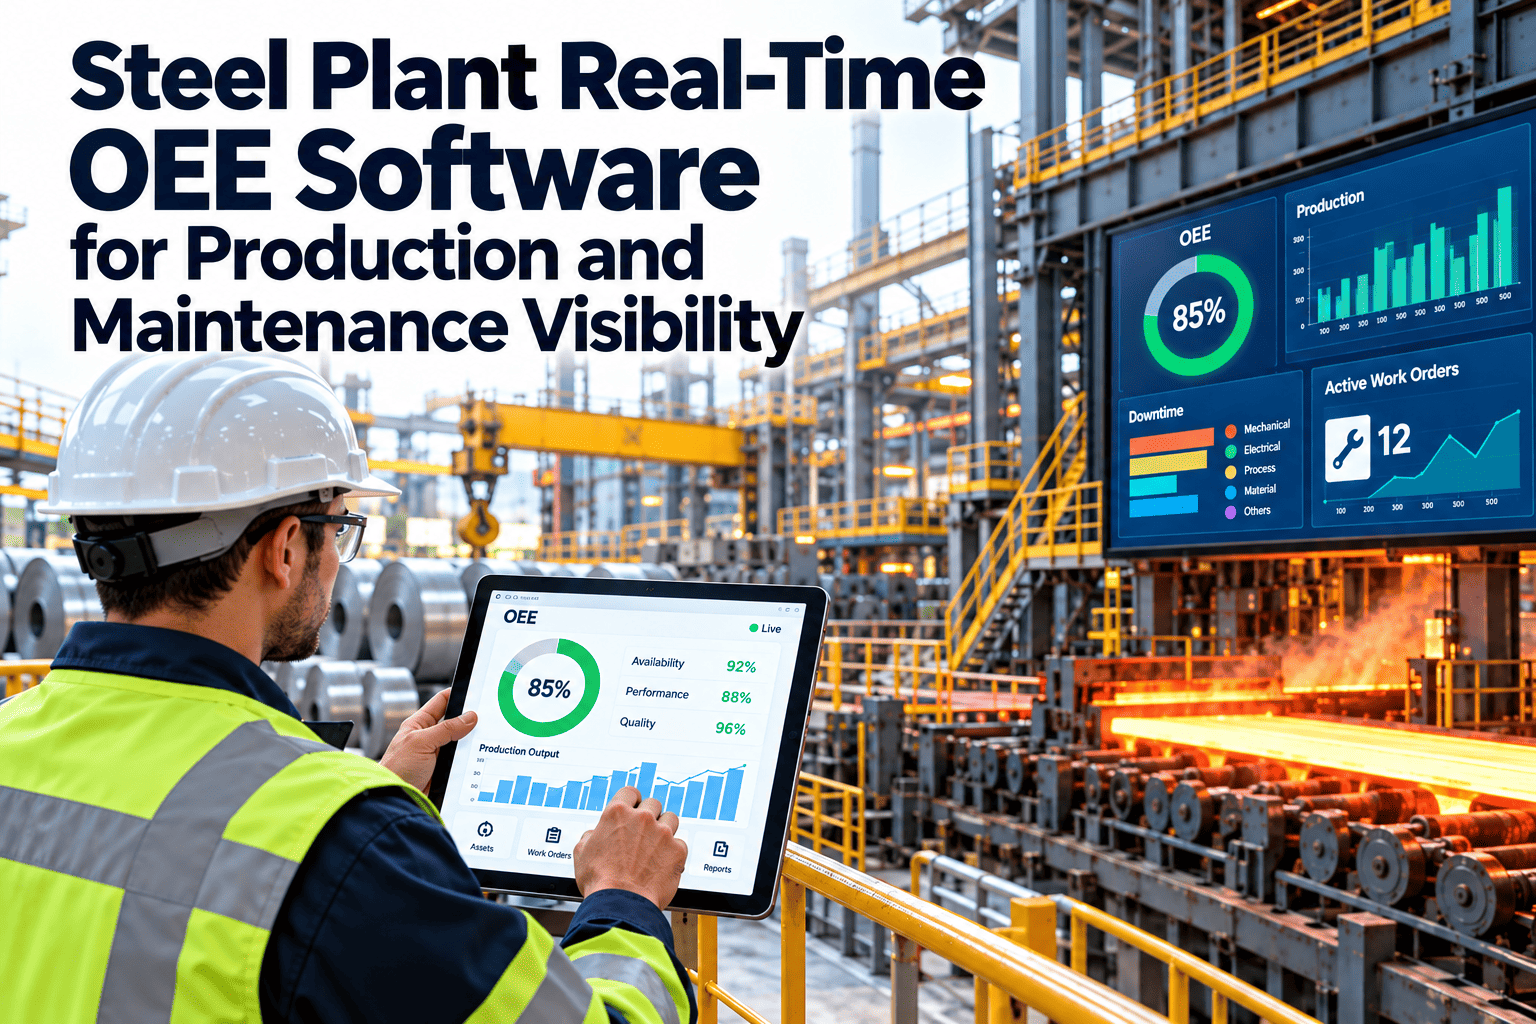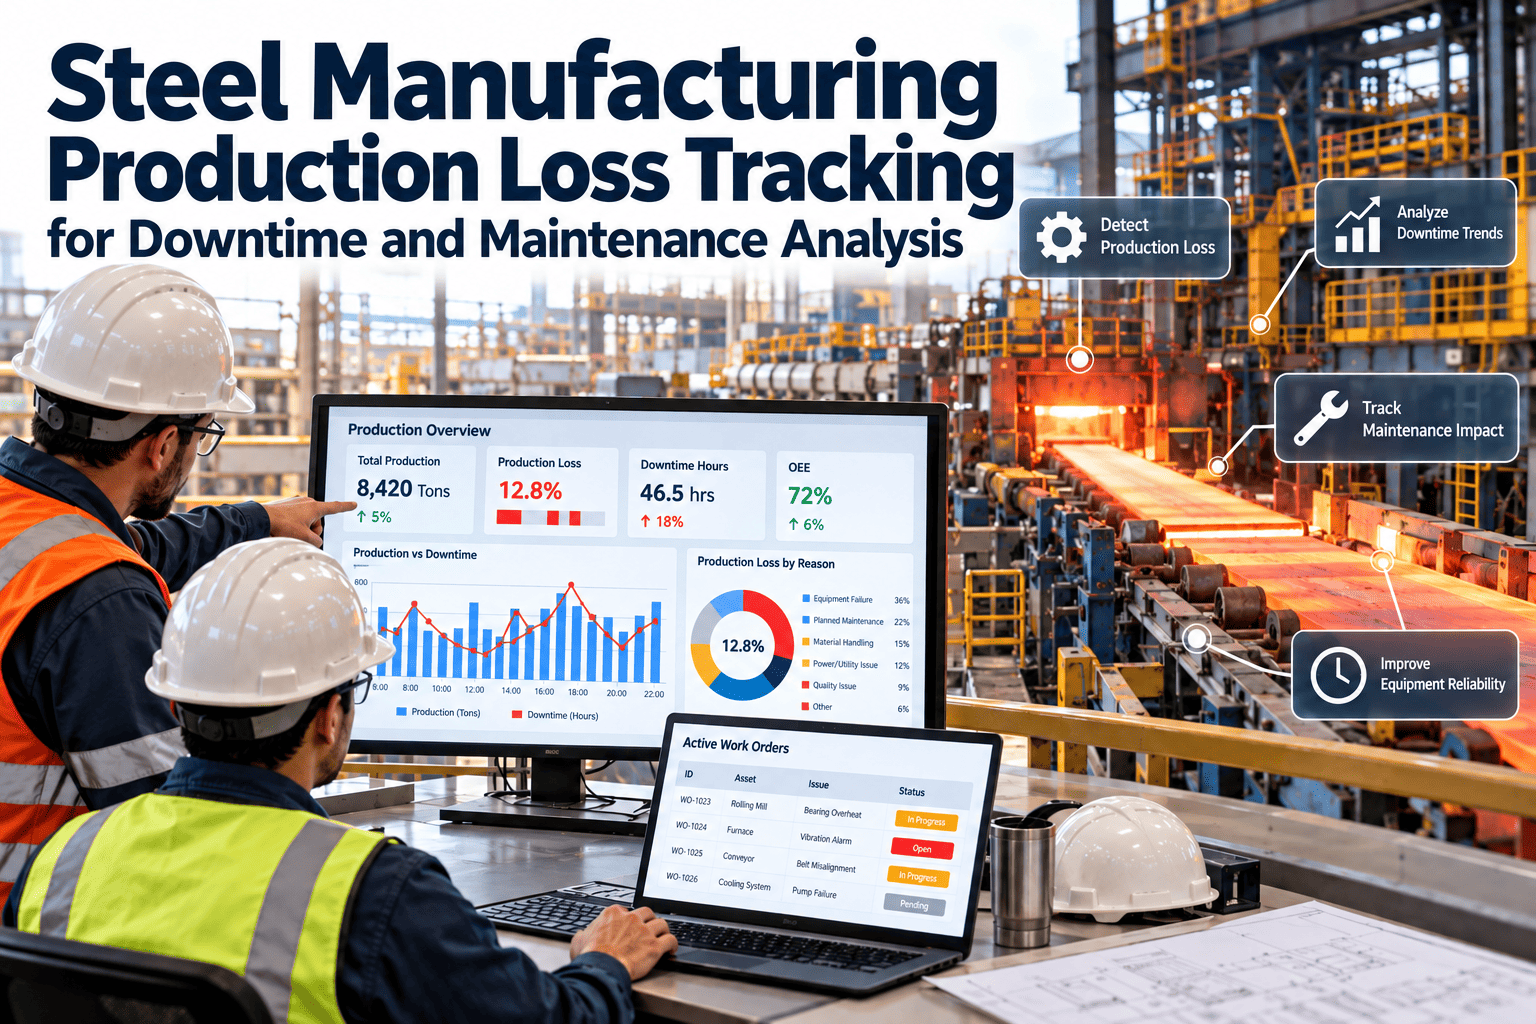
A plant-wide OEE number reported once a month tells management how the last period went, but it does little for the supervisor who must fix tomorrow's first shift. Shift-level OEE reporting shows where time, speed and yield were lost while the cause is still fresh and the people involved are still on site. This article explains how steel plants can build shift OEE reports that connect downtime, performance and quality losses to maintenance actions, using Oxmaint maintenance management software to keep the evidence and follow-up in one place.
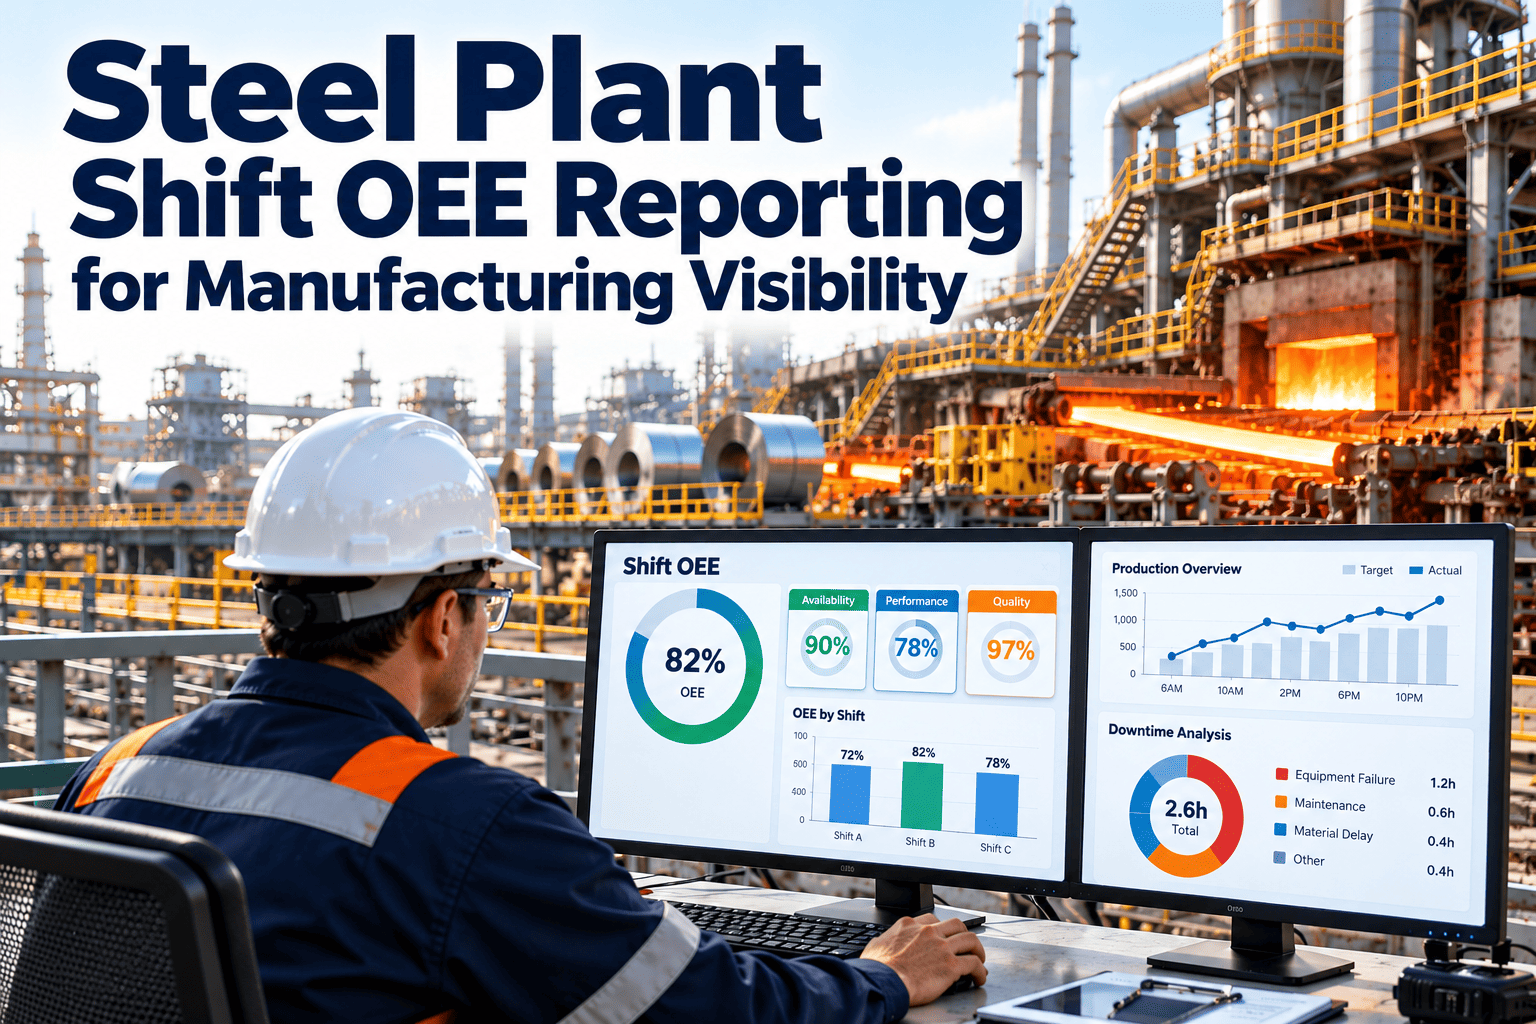
Steel Plant Shift OEE Reporting for Manufacturing Visibility
Give every shift a clear scorecard for availability, performance and quality, and turn each loss into an owned maintenance or process action before the next shift starts.
Why shift level matters more than the monthly average
- Problems repeat by shift, crew, product or day of week, and monthly averages hide those patterns.
- Operators and technicians remember causes on the same day, but not three weeks later.
- Maintenance can plan corrective work for the next shift instead of discovering the loss at month end.
- Supervisors gain a fair, shared scorecard that compares like with like, rather than arguing over opinions.
OEE is a diagnostic, not a trophy
The number matters less than the list of losses behind it. A shift report is useful when each loss has a category, a duration and an owner.
Anatomy of a useful shift OEE report
Keep the report to one screen or one printed page. The following blocks are enough for most steel areas.
The six big losses mapped to steel plant causes
Classic OEE groups losses into six categories. In steel, each category has familiar causes that maintenance and operations can recognise.
| Loss category | OEE factor | Typical steel plant causes | Maintenance response |
|---|---|---|---|
| Equipment failure | Availability | Drive trips, bearing failures, hydraulic leaks, cooling water problems | Corrective work order, root cause review, PM update |
| Setup and adjustment | Availability | Roll changes, mould or guide changes, grade or size changeovers | Standard work, tooling readiness checks |
| Minor stops | Performance | Sensor faults, jams, guide problems, short interlock trips | Inspection route, adjustment tasks, spare parts |
| Reduced speed | Performance | Worn equipment, thermal limits, vibration limits, cautious operation | Condition checks and targeted repair |
| Startup rejects | Quality | Warm-up scrap, tail and head ends, unstable first products | Startup checklists and calibration |
| Production rejects | Quality | Dimensional errors, surface defects, off-grade material | Gauge, guide and roll condition tasks |
A worked example with illustrative numbers
The figures below are invented to show the arithmetic, not to represent a benchmark. Replace them with your own ideal rate and planned time.
Notice that no single factor looks alarming, yet together they leave about a quarter of the planned time and capacity unused. The report should show which stops, slow periods and rejects account for each gap.
Steel-specific cautions when defining OEE
Decide what counts as planned time
Scheduled maintenance outages, reline periods and market-driven stops should be treated consistently, or comparisons become meaningless.
Set ideal rates carefully
Use a documented design or demonstrated best rate for each product group, not last month's average.
Handle continuous and batch units differently
A caster sequence, a rolling campaign and an arc furnace heat cycle each need their own definition of run time.
Respect upstream and downstream limits
A unit starved or blocked by its neighbour has lost time that is not its own fault, so record that cause separately.
From stop to action: the shift loss workflow
Capture the stop
The operator or system logs start time, end time and a first-level reason using a short pick list.
Classify the cause
The supervisor confirms the category, such as mechanical, electrical, process, material or waiting.
Raise or link a work order
Equipment related stops create a corrective job or attach to an existing one on the same asset.
Review at handover
Outgoing and incoming crews walk through the top losses and open actions in a short meeting.
Verify the result
After repair, check whether the loss disappeared and update the preventive plan if it repeats.
Designing stop reason codes that people will actually use
Codes fail when they are too many, too vague or too political. Aim for a short, layered list that reflects how the plant talks about problems.
- Limit the first level to five or six choices, and the second level to what operators can recognise in the moment.
- Include a clear choice for waiting on spare parts, because it exposes inventory problems.
- Review the most used code each month, since a large generic category usually hides specific causes.
Reporting rhythm: who needs what and when
| Cadence | Audience | Content | Decision supported |
|---|---|---|---|
| End of shift | Crew leader and supervisor | Scorecard, stops and top three losses | Handover priorities and next-shift tasks |
| Daily | Area manager and maintenance planner | Previous day by unit, open work orders | Planning of corrective work and access |
| Weekly | Production, maintenance and quality leaders | Loss Pareto, repeat failures, PM compliance | Action list and resource allocation |
| Monthly | Plant management | Trends by unit, product and crew | Investment, staffing and strategy choices |
Connecting OEE to maintenance KPIs
Before and after a connected shift report
Disconnected reporting
- Stops written on paper and typed later
- Reasons recorded as free text
- OEE calculated monthly in a spreadsheet
- Maintenance learns about problems from complaints
- Same loss appears every week with no owner
Connected reporting
- Stops captured at the time on a shared record
- Reasons chosen from a short, agreed list
- Scorecard ready at the end of every shift
- Work orders created and linked to the stop
- Repeat losses flagged with owner and due date
Ways to capture shift data, from simple to automated
Manual log on a mobile form
Operators enter stops and reasons on a phone or tablet. This is quick to start and works on older equipment, but it depends on discipline.
Semi-automatic capture
The control system detects a stop, and the operator selects the reason. Timing becomes accurate while the cause still comes from people.
Automated production feeds
MES or historian data supplies run time, rates and tonnes, and maintenance adds cause and repair details. Accuracy is high, but interfaces need care.
Most plants start manually on one bottleneck unit, learn which fields matter, and then automate the parts that are error-prone.
A fifteen minute handover agenda built on the report
- Read the scorecard and compare it with the target for the unit.
- Walk through the top three losses and what the crew saw first-hand.
- Confirm which losses already have a work order or process action.
- Identify items the incoming crew must monitor or avoid during the shift.
- Agree who updates the report and closes actions before the next handover.
The goal is a short, practical conversation. If the meeting turns into a debate about blame, the next report will quietly become less honest.
Using loss ranking to choose what to fix first
Rank losses by lost minutes or lost tonnes for the week, then look at the top few causes. A small number of repeating problems usually accounts for most of the loss, so concentrate effort there instead of spreading it across dozens of minor events.
- Separate frequent short stops from rare long failures, because they need different responses.
- Check whether the same asset appears in several categories, such as stops, slow running and rejects.
- Estimate the effect of fixing each cause before assigning resources.
- Re-run the ranking after repairs to confirm the loss actually moved.
Tying quality losses to equipment condition
Quality is often reported by the laboratory or inspection team, away from the maintenance conversation. Bring it into the shift report by recording the defect, the product and the suspected source, then link repeat defects to the equipment that influences them.
- Dimensional drift may point to roll wear, guide alignment or gauge calibration.
- Surface defects may point to cooling nozzles, scale handling or roll surface condition.
- Temperature related rejects may point to burners, thermocouples or furnace seals.
- Recurring startup scrap may point to checklist gaps or unstable setup practice.
Reading trends by crew, product and day
Once several weeks of reports exist, compare the same loss categories across crews, products and days of the week. Differences are rarely about effort. They usually reveal training gaps, uneven handovers, unstable materials or equipment that behaves differently under certain conditions.
By crew
Look for different stop reasons or response times, then share the practices of the best performing handover.
By product
Check whether certain grades or sizes drive slow running or rejects, and adjust ideal rates accordingly.
By day and time
Patterns after weekends or at shift change may point to restart issues or missing preparation.
What good looks like after one quarter
- Every shift produces a report within minutes of handover, and supervisors trust the numbers.
- The top five losses for each unit are known, owned and tracked to closure.
- Equipment stops can be traced to assets, work orders and repair history without searching.
- Planners use shift data when scheduling preventive work and short corrective jobs.
- Definitions are stable enough that month-on-month comparisons are meaningful.
Mistakes that make shift OEE unreliable
A thirty day pilot on one unit
Week one: define
Agree planned time rules, ideal rates and the stop reason list with operations and maintenance.
Week two: capture
Begin logging stops and quality losses on every shift, and link equipment stops to assets.
Week three: review
Hold daily handovers using the report, and create work orders for the largest equipment losses.
Week four: adjust
Simplify codes, correct definitions and decide whether to extend the report to the next unit.
Shift OEE reporting checklist
- Planned time rules are documented for every unit
- Ideal rates are defined by product group and approved
- Stop reasons use a short, layered pick list
- Operators can log stops from the line or a nearby device
- Quality losses carry defect codes and tonnes
- Equipment stops link to assets and work orders
- Handover meetings use the same one-page report
- Top losses are reviewed weekly with maintenance and production
- Definitions are reviewed when equipment or products change
How Oxmaint supports shift-level visibility
Oxmaint covers the maintenance side of the loop: what failed, what was done and whether it came back. OEE calculations and production rates usually come from MES or production systems, so confirm how they should connect to your maintenance record.
- Asset records and hierarchies that match the units shown on the scorecard.
- Work orders and requests created from stops, with priorities, checklists and photos.
- Preventive schedules and inspections that address recurring minor stops and slow running.
- Spare parts tracking that reduces waiting time in the loss ledger.
- Dashboards and reports on backlog, repeat failures and compliance by unit.
Frequently asked questions
What is a good OEE for a steel plant?
It depends on process and product. Compare units with their own history first and use published figures cautiously.
Should planned outages count against OEE?
Define it once and apply it consistently. You can book a demo to discuss your rules.
Who should log stops?
Operators at the time of the event, with supervisors confirming the cause at handover.
Can maintenance data improve OEE?
Yes, through repair history, condition checks and parts availability that cut stops and slow running.
Where should we start?
Choose one bottleneck unit and pilot the report. You can sign up to set up its assets.