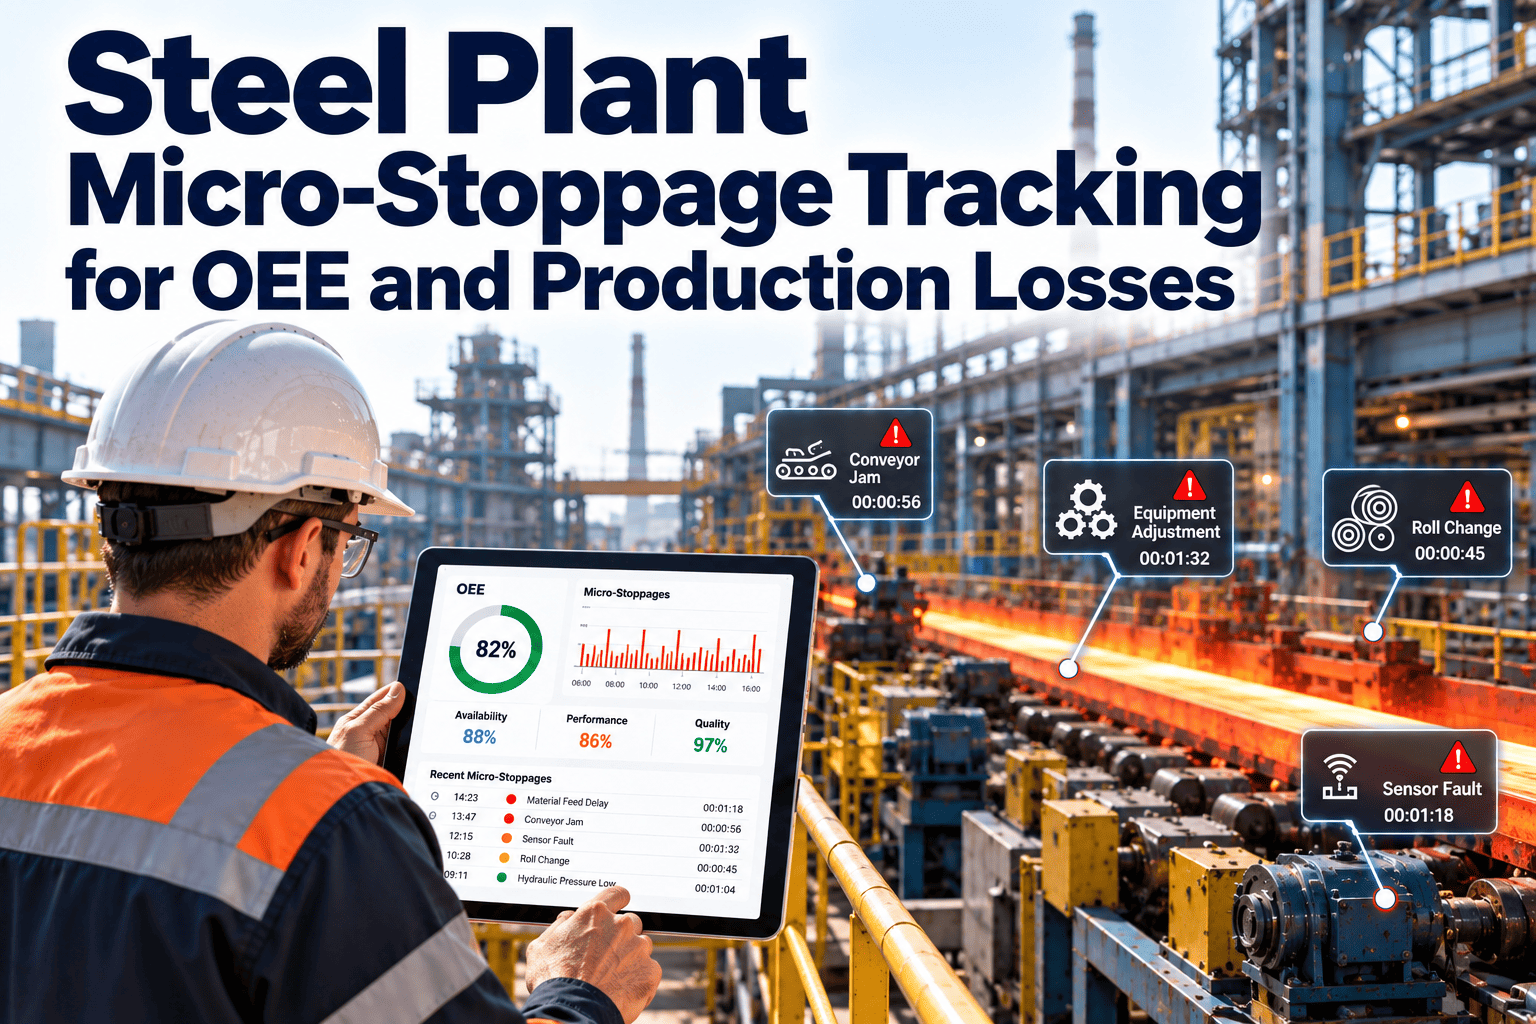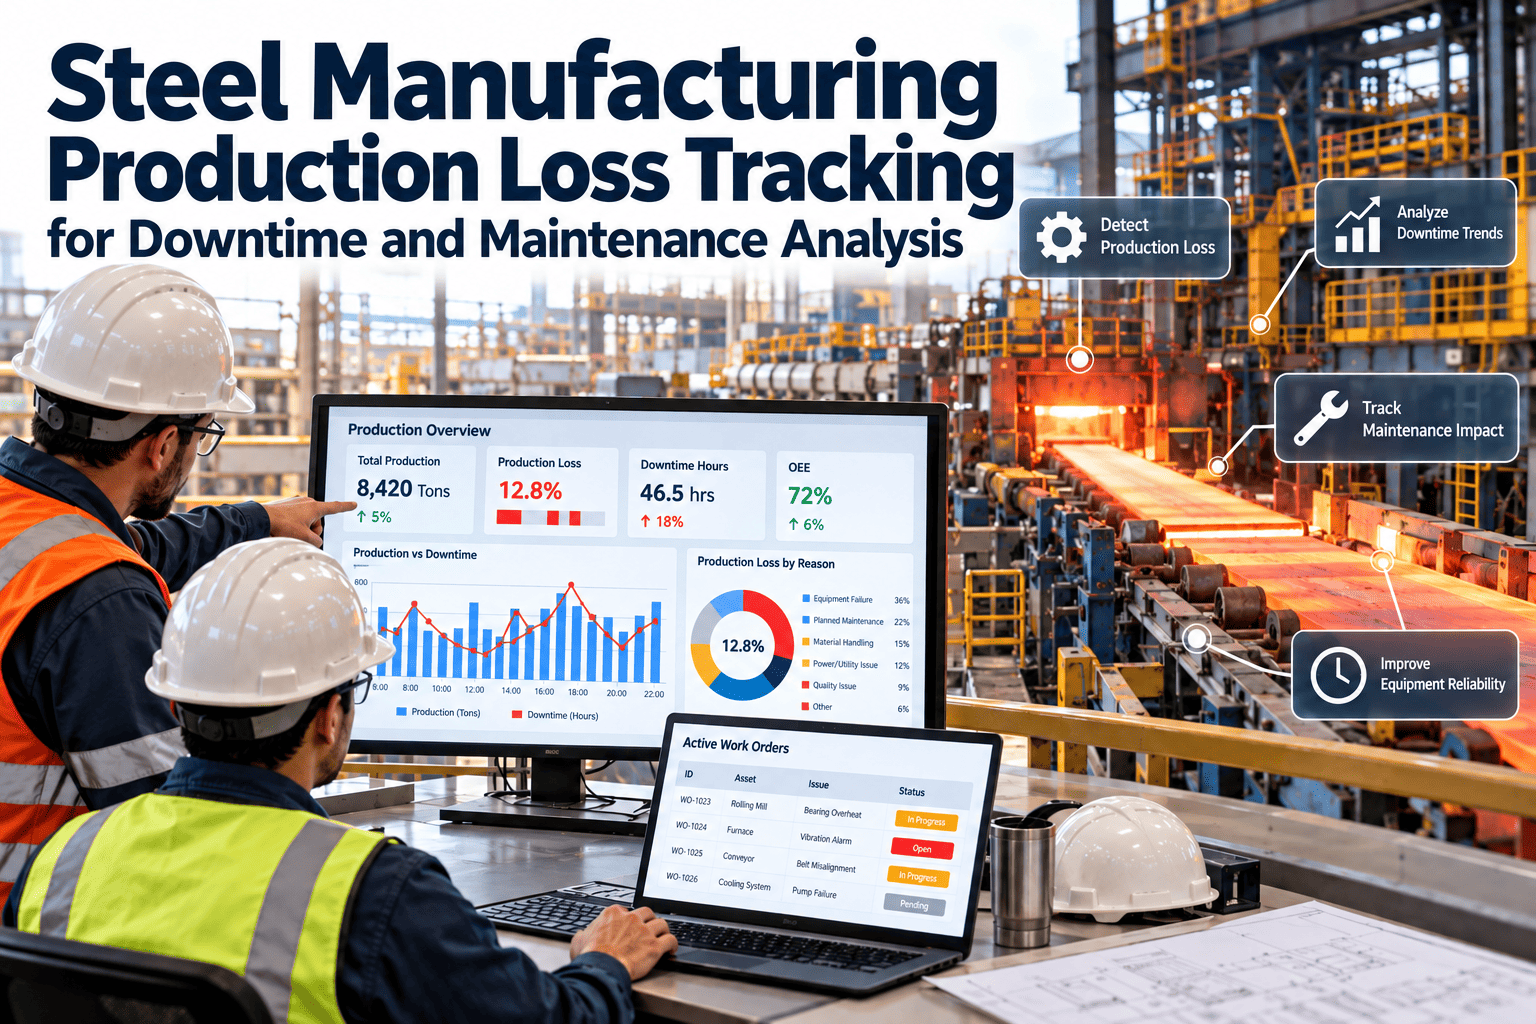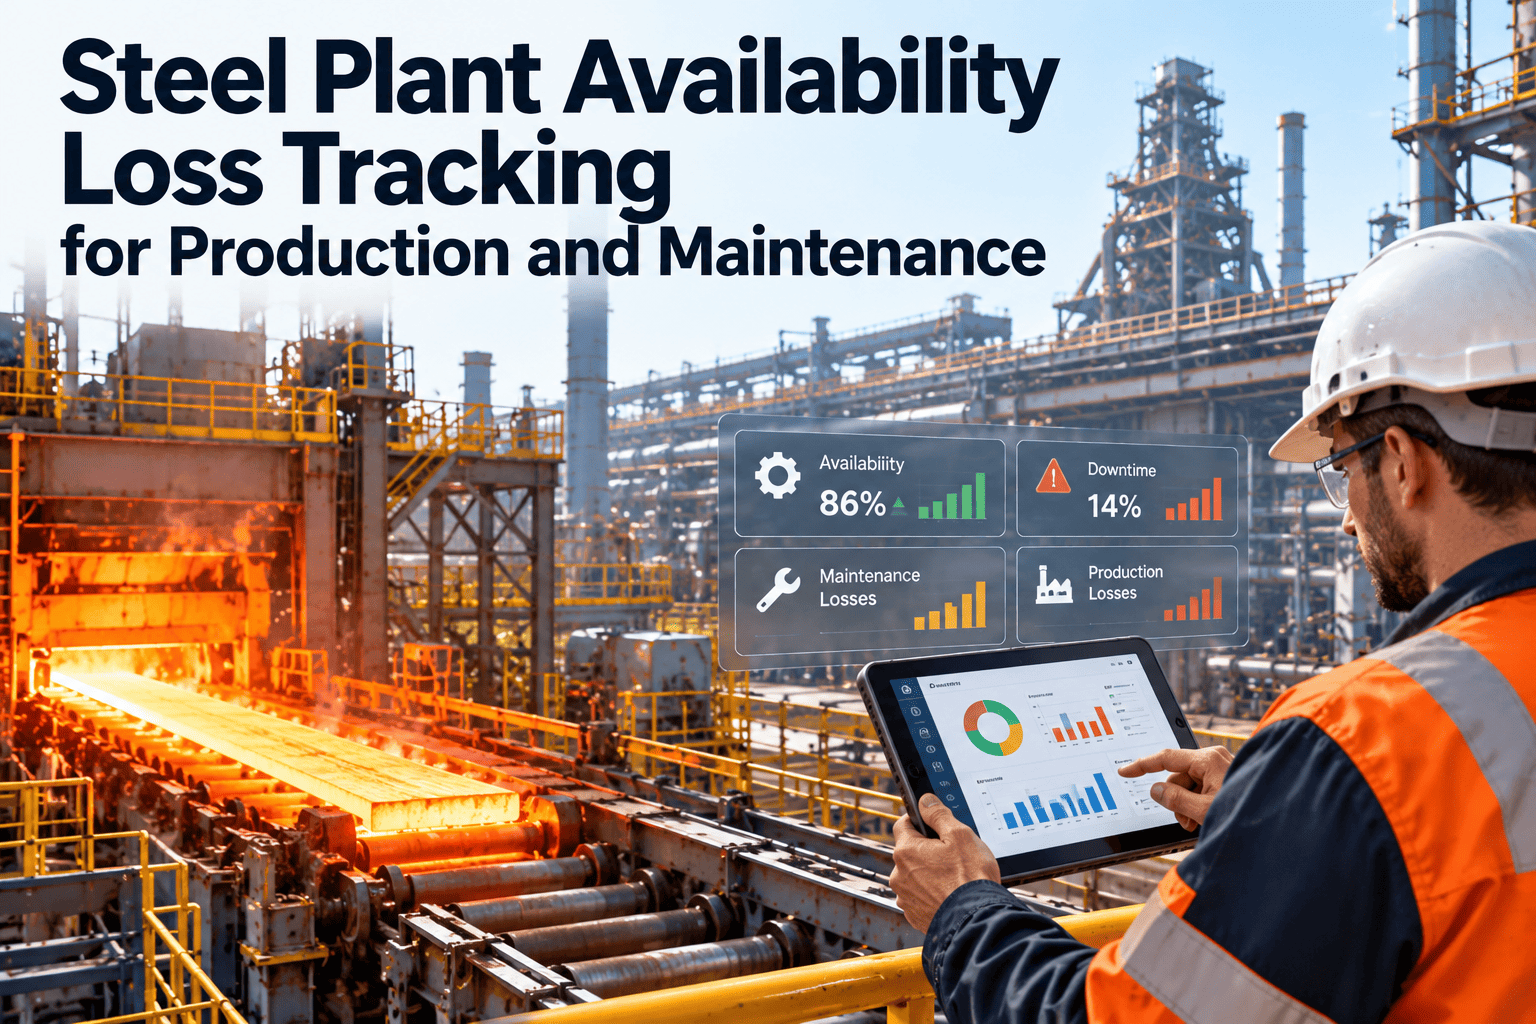
When a steel line is not running, two teams usually describe the same hour in different words. Production calls it a delay, maintenance calls it a breakdown, and the log often holds a single vague reason that fits neither view. Availability loss tracking fixes this by recording every minute of lost run time against a shared set of reasons, so the loss can be tied to equipment, cause and action. This guide shows how to structure that tracking for steel plants, link downtime to OEE and connect each loss to a maintenance response. To record lost time on the same work orders that fix it, you can connect downtime to maintenance in Oxmaint.
Steel Plant Availability Loss Tracking for Production and Maintenance
Break the planned production hour into run time and named losses, then give production and maintenance one version of what went wrong and what to do next.
What availability loss means in OEE
This page focuses on the first factor, because availability is where maintenance and production overlap most. The six big losses framework places breakdowns and setup or adjustment time in availability, small stops and reduced speed in performance, and startup and production rejects in quality.
The loss tree: from a stopped line to an owner
Equipment failure
Unplanned stops caused by a breakdown. Owner: maintenance.Setup and adjustment
Roll changes, grade changes, tooling. Owner: production with maintenance support.Process and supply stops
Waiting for material, upstream delay, utilities. Owner: operations.Planned stops
PM, inspection, scheduled shutdown. Owner: maintenance planner.Whether planned stops count against availability depends on how your site defines planned production time. Agree the definition first and apply it everywhere.
Why most downtime logs cannot be trusted
One-word reasons
Entries like "mechanical" or "electrical" hide whether it was a bearing, a sensor or a drive.Two systems, two stories
The production log and the maintenance work order disagree on start time, end time and cause.Short stops disappear
Stops under a few minutes are rarely logged, though together they can cost more than a rare long breakdown.Late entry
Reasons typed at end of shift rely on memory, so cause and duration are approximate.No equipment link
Losses are recorded against a line, not an asset, so repeat offenders stay hidden.Build a reason code structure people can use
| Level | What it answers | Illustrative entries |
|---|---|---|
| 1. Loss category | Which family of loss is this? | Equipment failure, setup, supply, planned stop, external |
| 2. Area and asset | Where did it happen? | Caster line 2, oscillation drive, tag from the asset register |
| 3. Failure mode | How did it fail? | Overheating, seized, leak, trip, wear, loss of signal |
| 4. Cause | Why did it fail? | Lubrication, overload, contamination, installation, operation |
| 5. Action | What was done? | Replaced, repaired, adjusted, reset, deferred |
Keep lists short
Long picklists get ignored. Aim for options an operator can choose in seconds.
Use shared definitions
Production and maintenance agree what each reason means, in writing.
Link to the asset register
Pick the equipment from a list, so losses roll up by tag, area and class.
One record for the stop, the cause and the repair
Oxmaint ties downtime events to assets and work orders, so lost run time and the fix sit together in one history.
A tracking workflow from stop to improvement
Detect the stop
Operator or line signal marks the start time.Open the event
Select category and asset, and raise a work order if repair is needed.Diagnose and repair
Technician records mode, cause and action at close-out.Close the event
Both teams confirm end time and reason.Review weekly
Rank losses by lost time and frequency.Assign an action
Name an owner and date for the top few causes.The close-out step matters most. A downtime record with a duration and no recorded cause adds little. A short, structured entry turns every stop into evidence.
Typical availability losses along the steel route
| Area | Common availability losses | Maintenance response |
|---|---|---|
| Raw materials and sinter | Conveyor trips, chute blockage, crusher jams | Idler and belt inspection routes, wear checks |
| Blast furnace | Stove valve faults, blower trips, cooling failures | Condition monitoring and valve PM |
| Melt shop | Electrode and transformer faults, crane delays, ladle turnaround | Inspections and spare readiness for key items |
| Casting | Segment bearing issues, oscillation faults, breakouts | Bearing monitoring and planned segment changes |
| Rolling mills | Roll changes, drive trips, gearbox faults, cobbles | Roll shop planning and drive condition checks |
| Utilities | Compressor, pump and water system failures | Standby changeover checks and PM |
Which loss deserves attention first
Frequent and long
Top priority. Run root cause analysis and fix the failure mode.Rare but long
Improve spares, response plans and condition monitoring.Frequent but short
Look for small stop patterns and quick standard fixes.Rare and short
Monitor only. Do not spend improvement effort here.Reliability measures that sit beside availability
MTBF
Mean time between failures. Shows how often an asset stops.MTTR
Mean time to repair. Shows how long each stop lasts, including waiting.Planned versus reactive
Share of labour on planned work. A falling share often precedes more stops.PM compliance
Whether preventive work is done on time on critical assets.Repeat failure rate
How often the same asset fails in the same way.Production and maintenance: one meeting, one set of numbers
When the teams track separately
- Each side defends its own numbers
- Reasons are reclassified after the fact
- Priorities depend on who speaks loudest
- Action items lack a clear owner
When they share one record
- The same stop appears with one start, end and cause
- Reviews rank losses from the same data
- Maintenance actions follow the biggest losses
- Progress is visible week to week
How Oxmaint supports availability loss tracking
Work orders
Record failure mode, cause, action and time on the same job that restores the equipment.
Asset management
Roll losses up by tag, area and class so repeat offenders stand out.
Preventive maintenance
Turn recurring loss causes into PM tasks and track compliance on critical assets.
Inspections and mobile
Capture early warning findings and stop details from the shop floor.
Dashboards
Review downtime, MTBF, MTTR and backlog in one view for the weekly meeting.
Agree what counts before you count it
Planned production time
State which hours are scheduled for production. Decide whether holidays, planned shutdowns and no-demand periods are inside or outside it.
Minimum stop length
Set a threshold for logging a stop, and a separate way to record frequent short stops below it.
Start and end of a stop
Define when a stop starts, such as the line signal, and when it ends, such as stable production.
Planned versus unplanned
Write the rule for classifying a stop, so the same event never lands in two categories.
Owner of each category
Name who is accountable for each loss family so actions have a home.
Write these rules down and share them with every shift. Most disputes in a downtime review come from different definitions, not from different facts.
Short stops: the loss that hides in the average
Why they go unrecorded
- Operators clear the fault and restart without logging
- The log form takes longer than the stop
- Each stop looks too small to matter
- No one reviews them, so no one asks for them
How to bring them into view
- Use a one-touch reason selection at the line
- Where possible, capture stops from the control system
- Count frequency as well as total minutes
- Review the most frequent short stops weekly
Ways to capture downtime data
| Method | How it works | Strength | Weakness |
|---|---|---|---|
| Manual logbook | Operators write stops and reasons on paper | Simple, no setup | Late entry, gaps, hard to analyse |
| Digital form on a device | Operator selects reason from a short list | Structured, searchable, linked to assets | Still depends on the person entering |
| Semi-automatic | Control system detects the stop, operator adds the reason | Accurate timing, reason from the person who knows | Needs integration work and reason discipline |
| Fully automatic | Signals classify stops with rules | Consistent and complete | Rules miss context, so some review is needed |
Most plants start with a digital form and move toward semi-automatic capture as signals and asset records become reliable.
From ranked losses to action
Rank by lost time
List causes from most to least minutes lost over a period.Rank by frequency
Frequent small stops can outrank rare large ones in effect.Pick the top few
Focus on a short list so action is real, not scattered.Find the cause
Use failure history and a root cause method on each one.Choose a fix
Design change, PM task, inspection, spare, training or procedure.Confirm the result
Check that the loss falls in the following weeks.Closing the loop is what makes tracking worth the effort. Every top loss should leave the review with an owner, a due date and a way to verify that the fix worked.
A weekly loss review agenda
| Agenda item | What to look at | Output |
|---|---|---|
| Last week's stops | Top losses by time and frequency, by area | Agreed ranking |
| Repeat failures | Assets with the same failure mode again | Root cause request |
| Open actions | Status of earlier assigned fixes | Updated owners and dates |
| Data quality | Stops with missing cause or asset | Clean-up tasks |
| Coming week | Planned stops, PMs and parts readiness | Confirmed plan |
Mistakes that weaken availability tracking
Chasing a single OEE number
A headline figure hides which loss moved. Always read it beside the loss breakdown.
Blaming people for the log
If entries lead to blame, operators will pick safe reasons. Use the data to fix equipment and process.
Too many reason codes
Long lists produce random picks. Keep the first level short and refine causes at close-out.
Ignoring waiting time
Time waiting for parts, permits or crews is often larger than the repair itself and has its own fix.
No link to PM
If a recurring cause never changes a PM task, the cycle of loss will repeat.
A worked availability example
The figures below are illustrative for a single shift on one line. They show how recorded losses turn into an availability figure and a ranked list for action.
| Item | Illustrative minutes | Comment |
|---|---|---|
| Planned production time | 480 | Eight scheduled hours |
| Equipment failure | 45 | Drive trip, one long event |
| Setup and adjustment | 30 | Roll change and checks |
| Waiting for material | 20 | Upstream delay |
| Run time | 385 | 480 minus 95 minutes of loss |
| Availability | About 80 percent | 385 divided by 480 |
Ranking these losses shows the drive trip as the largest single item, but one week of data is needed before deciding if it is a pattern.
Turning a recurring loss into a maintenance change
| Recurring loss pattern | Likely maintenance response | How to confirm it worked |
|---|---|---|
| Repeated bearing failures on one drive | Review lubrication, alignment, and add a condition check | Longer time between failures on that tag |
| Trips after cleaning or washdown | Inspect enclosures, seals and connectors, add a post-wash check | Fewer trips following washdowns |
| Long repairs waiting for parts | Review criticality and stock for the parts involved | Shorter waiting time per event |
| Frequent short sensor faults | Add sensor checks and cleaning to routine rounds | Lower count of short stops |
| Late response at night | Review callout rules, crew skills and job instructions | Faster response across shifts |
Measures for the loss tracking program itself
Stops with a complete record
Share of stops with an asset, category and cause. Aim to raise it each month.
Time to close an event
How quickly stop records are finished after the line restarts.
Actions closed on time
Share of assigned fixes finished by the agreed date.
Top loss trend
Movement of the largest losses over several weeks, which shows real progress.
Frequently asked questions
What is availability loss in a steel plant?
It is planned production time lost to stops such as breakdowns, setups and waiting. It is the availability factor in OEE.
How is availability calculated?
Divide run time by planned production time. Define planned time clearly so both teams count stops the same way.
Should planned maintenance count as a loss?
That depends on your site definition. Track it under its own category either way. You can book a demo to see categories applied.
How do we capture short stops?
Use a simple, fast entry method and clear minimum duration rules. Short stops matter because they add up across shifts.
Can a CMMS replace an OEE system?
It supports it by linking downtime to assets and repairs. You can get started and connect loss records to work orders.
Turn every lost minute into a maintenance action
Give production and maintenance one record of what stopped, why it stopped and what was done, then fix the biggest losses first.