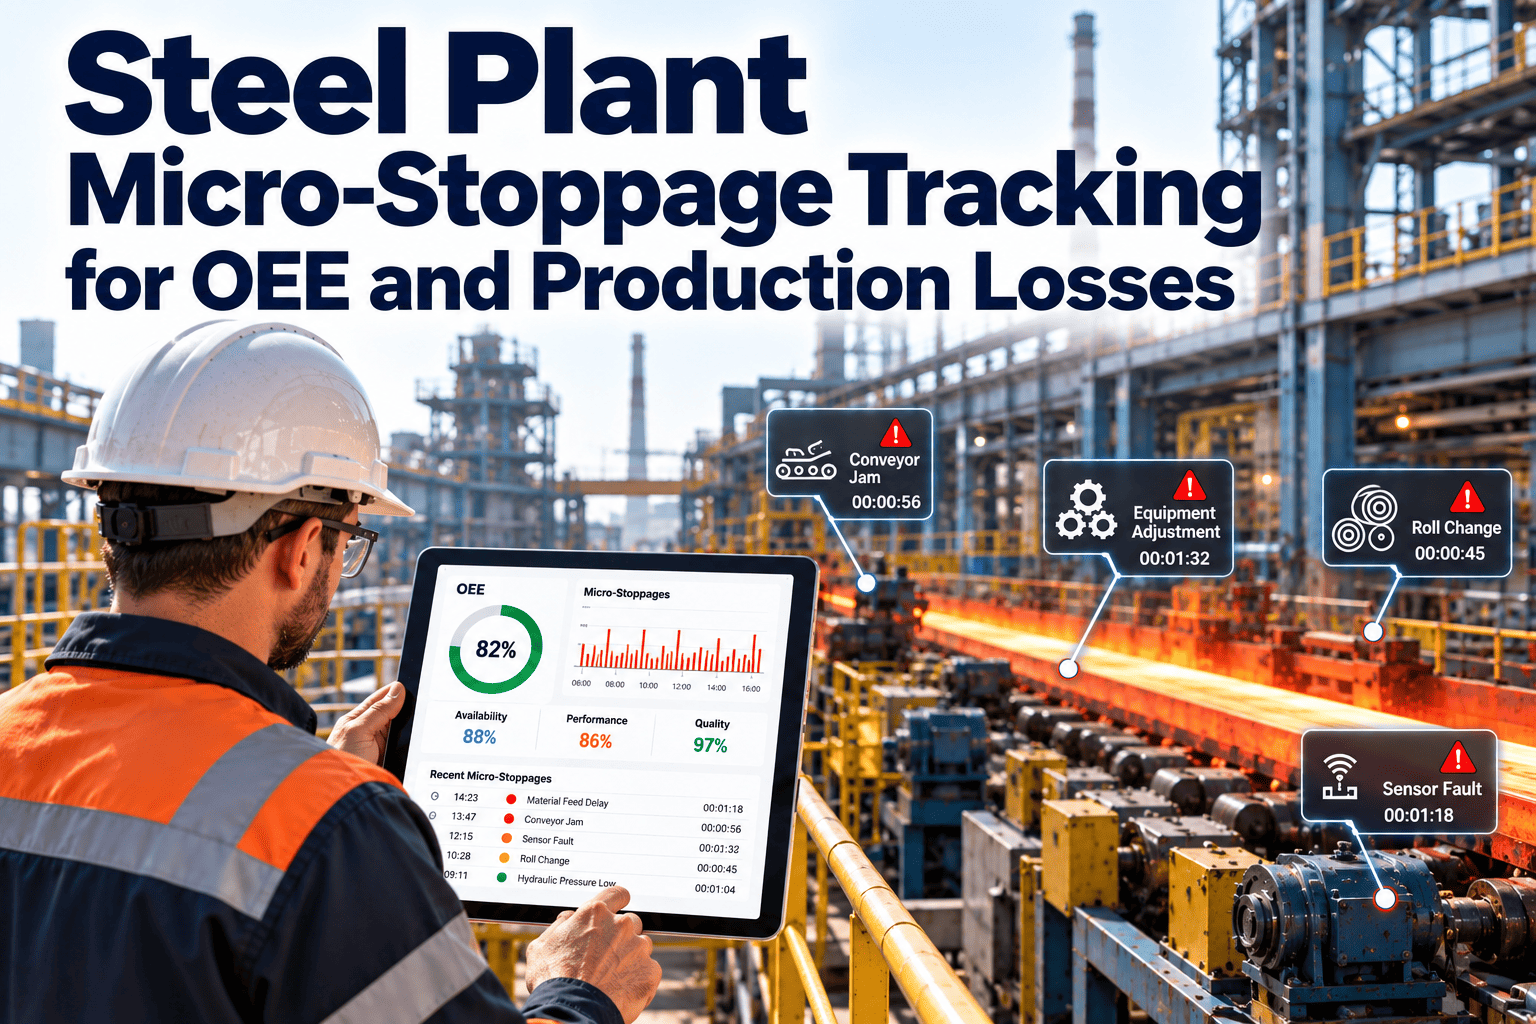
Big breakdowns get investigated, but short stops often slip past unnoticed. A strip stops for forty seconds at a coil handling station, a caster waits on a ladle turret signal, a pinch roll trips and resets. Each event looks harmless, yet together they quietly erode throughput and hide the real causes of lost time. Micro-stoppage tracking exposes these small losses, connects them to equipment and shifts, and feeds the fixes into planned work through a steel plant CMMS so they stop repeating.
Steel Plant Micro-Stoppage Tracking for OEE and Production Losses
Capture short stops, slow running and quality losses by asset and cause, then turn each pattern into a maintenance action that protects line performance.
What counts as a micro-stoppage in a steel plant
- A micro-stoppage is a short, often self-clearing interruption, defined by a plant-set time threshold.
- Many are never recorded because operators reset the equipment and carry on.
- Depending on the threshold, they land in availability or performance loss, which is why they distort OEE.
- Slow running below the target rate is related but different, and should be tracked separately.
Why short stops are hard to see in steel
Continuous process masks them
Buffers, accumulators and slower speeds absorb brief stops, so nobody notices the loss in the moment.Manual logs miss detail
Operators record major delays at shift end, and short events are forgotten or grouped as "other".Ownership is unclear
Operations sees a process issue while maintenance sees a symptom, so nobody owns the cause.Data lives in separate tools
PLC counters, MES delays and work orders use different asset names and cannot be compared easily.Where micro-stops hide along the steel line
Typical sources differ by process area. Use the table as a starting list for your own review, not as a prediction.
| Area | Common short-stop sources | Likely maintenance link |
|---|---|---|
| Melt shop and ladle handling | Crane or turret interlock trips, sensor faults, slide gate delays | Limit switch condition, calibration, hydraulic checks |
| Continuous caster | Strand alarms, mold level control trips, cooling circuit faults | Sensor wear, valve response, roll and bearing condition |
| Hot rolling | Cobble prevention stops, looper faults, descaler or pinch roll trips | Drive tuning, lubrication, hydraulic leakage |
| Cold rolling and finishing | Strip tracking errors, welder faults, coil entry and exit jams | Guide alignment, encoder health, mechanical wear |
| Coil handling and packing | Conveyor sensor trips, strapping jams, stacker faults | Sensor cleaning, belt and chain condition, component replacement |
Micro-stops, slow running and minor defects compared
| Loss type | What it looks like | OEE category | How to capture it |
|---|---|---|---|
| Micro-stoppage | Short halt that clears quickly after a reset or adjustment | Availability or performance, depending on your threshold | Stop signal with duration and a reason code |
| Slow running | Line runs below its target rate without stopping | Performance | Compare actual speed with the ideal rate by product |
| Minor quality loss | Short periods of off-spec output after a stop or restart | Quality | Link restarts to downstream inspection results |
| Breakdown | Longer stop needing a repair crew | Availability | Work order with cause, labor and parts |
Reading a Pareto chart of short stops
A Pareto view ranks stop causes so teams fix the few that matter first. Build two versions, because frequency and lost time often tell different stories.
Rank by number of stops
Shows nuisance events that interrupt flow and frustrate crews, even when each one is brief.Rank by lost minutes
Shows which causes consume the most production time and deserve engineering effort.Split by asset and shift
Reveals whether a problem is tied to one machine, one product or one working practice.Compare before and after
Confirms that a corrective action reduced the targeted cause instead of moving it elsewhere.From stop event to prevented loss
Manual versus automatic capture
Manual logging
- Low cost and quick to start
- Good for adding human context
- Misses short or frequent events
- Depends on discipline across shifts
Automatic detection with operator coding
- Records every stop and its true duration
- Operator only adds the reason
- Needs reliable signals and tag mapping
- Gives data strong enough to rank causes
Many plants begin with manual capture on one bottleneck, then add signals once the reason codes are proven useful.
Build a reason code tree people will actually use
Equipment
- Sensor or switch fault
- Drive or motor trip
- Hydraulic or pneumatic issue
- Mechanical jam or wear
Process
- Upstream starvation
- Downstream blockage
- Material or strip condition
- Parameter out of range
People and planning
- Changeover or setup
- Waiting for crew or crane
- Missing spare or consumable
- Procedure unclear
Keep the list short enough to choose from in a few seconds, and review the "other" category monthly.
Linking micro-stops to maintenance actions
| Pattern seen in the data | Probable cause | Maintenance response |
|---|---|---|
| Same sensor trips repeatedly | Dirt, vibration, misalignment or cable wear | Add a cleaning and alignment inspection to preventive maintenance |
| Stops cluster at start of shift | Warm-up, lubrication or handover gaps | Revise start-up checks and handover tasks |
| Stops rise before a failure | Early bearing, drive or hydraulic degradation | Trigger condition-based inspection and plan the repair |
| One crew records far more stops | Different practices or coding habits | Standardize procedures and retrain on reason codes |
| Waiting for parts shows up often | Stock or reorder gaps | Adjust inventory minimums for critical spares |
Root cause methods that suit recurring short stops
5 Whys on the top cause
Ask why repeatedly until the answer is a condition you can change, such as a missing cleaning task or a worn guide.Fault tree for complex trips
Map every signal and interlock that can trip a station, then test each branch against recorded events.Time-pattern analysis
Check whether stops follow a shift, product change, ambient temperature or time since the last lubrication task.Failure mode review
Use FMEA-style thinking to decide which stops are early warnings of a bigger failure.Check the signal before trusting the stop count
Bad signals create false stories. Validate the data source before presenting results to operations.
- Confirm the stop signal matches what operators actually see on the line.
- Check timestamps and clock alignment between the PLC, MES and maintenance system.
- Remove planned stops, such as scheduled breaks and changeovers, from the micro-stop count.
- Watch for counters that reset or double count after a controller restart.
- Record any bypassed sensors, since they hide real events.
Shift handover and ownership
Operators contribute
- Choose the reason code at the time of the stop
- Note what was done to restart the line
- Flag repeating issues at handover
- Join short reviews of top causes
Maintenance contributes
- Turns recurring causes into work orders
- Adds inspection tasks for known weak points
- Reports back what was found and fixed
- Updates preventive schedules from results
Naming one owner per top cause, with a due date, prevents the same stop from appearing on every review without progress.
Four-week pilot on one bottleneck
Common mistakes in micro-stoppage programs
- Using too many reason codes, which pushes operators to choose "other".
- Collecting data without a regular review, so nothing changes on the floor.
- Blaming individuals instead of looking at equipment and process conditions.
- Fixing symptoms, such as resetting a trip, without a maintenance task to prevent it.
- Comparing lines without noting different products, speeds and thresholds.
- Declaring success from OEE alone without checking whether the targeted causes fell.
Connecting stop data to TPM and reliability routines
Setting thresholds and targets that fit your line
Choose one stop-length rule
Decide the duration that separates a micro-stop from a breakdown, and keep it fixed for each line so trends stay comparable.Define the ideal rate by product
Different grades and gauges run at different speeds, so one target rate can overstate or hide performance loss.Separate planned and unplanned time
Breaks, changeovers and scheduled maintenance should not be counted as stoppage losses.Set improvement goals per cause
Aim to reduce the top three causes rather than chasing one overall OEE figure.What a good weekly stop review looks like
Maintenance tasks that commonly reduce short stops
| Stop source | Preventive task to consider | Record to keep |
|---|---|---|
| Proximity and photoelectric sensors | Cleaning, mounting check and alignment verification | Condition found and any replacement |
| Conveyors and roller tables | Chain tension, roller bearing and guide inspection | Wear measurements and adjustments |
| Hydraulic units | Leak checks, filter changes and pressure verification | Pressure readings and oil condition |
| Drives and motors | Thermal check, connection tightness and fan cleaning | Temperatures and trip history |
| Lubrication points | Route-based greasing with correct quantity and interval | Completion and abnormal findings |
Before and after: handling a repeating sensor trip
Before a tracking routine
- Operator resets the trip and the line restarts
- The stop is not logged, or is logged as "other"
- Maintenance hears about it only after a longer failure
- The same sensor trips again on the next shift
- Nobody can say how often it has happened
After a tracking routine
- Every trip is recorded with duration and reason
- The weekly review shows the sensor in the top causes
- A work order checks mounting, cabling and cleaning
- A recurring inspection is added to preventive maintenance
- Stop counts confirm whether the fix worked
Questions to ask when stop data looks wrong
- Are planned stops being counted as losses, or are real stops hidden in them?
- Do operators on every shift use the reason codes the same way?
- Has a sensor, counter or controller setting changed recently?
- Does the product mix explain the difference between lines?
- Is the maintenance record updated after each corrective action?
Metrics to track alongside OEE
A quick-win checklist for the first month
- Pick one bottleneck line and one stop-length threshold.
- Agree a reason code list of around twelve to fifteen entries.
- Match stop signals to registered asset IDs.
- Hold a ten-minute daily review of the top three causes.
- Raise a work order for each cause that has a clear action.
- Check results after two weeks and remove unused codes.
How Oxmaint supports the loss-reduction loop
Oxmaint maintenance management software connects loss findings to the work that removes them.
Frequently asked questions
What stop length counts as a micro-stoppage?
There is no universal value. Set a threshold per line, such as a few minutes, and apply it consistently.
Do micro-stops really affect OEE that much?
They can, because frequency adds up quickly. Measure your own line before assuming their size.
Can maintenance own this without a new OEE system?
Yes, to start. Use reason codes and work orders, then set up your workflow and add signals later.
How do we stop operators skipping reason codes?
Keep the list short, show the data back to crews and act on the top causes so the effort visibly pays off.
Can this be demonstrated on our line?
Yes. Book a demo and bring a recurring stop as the example.