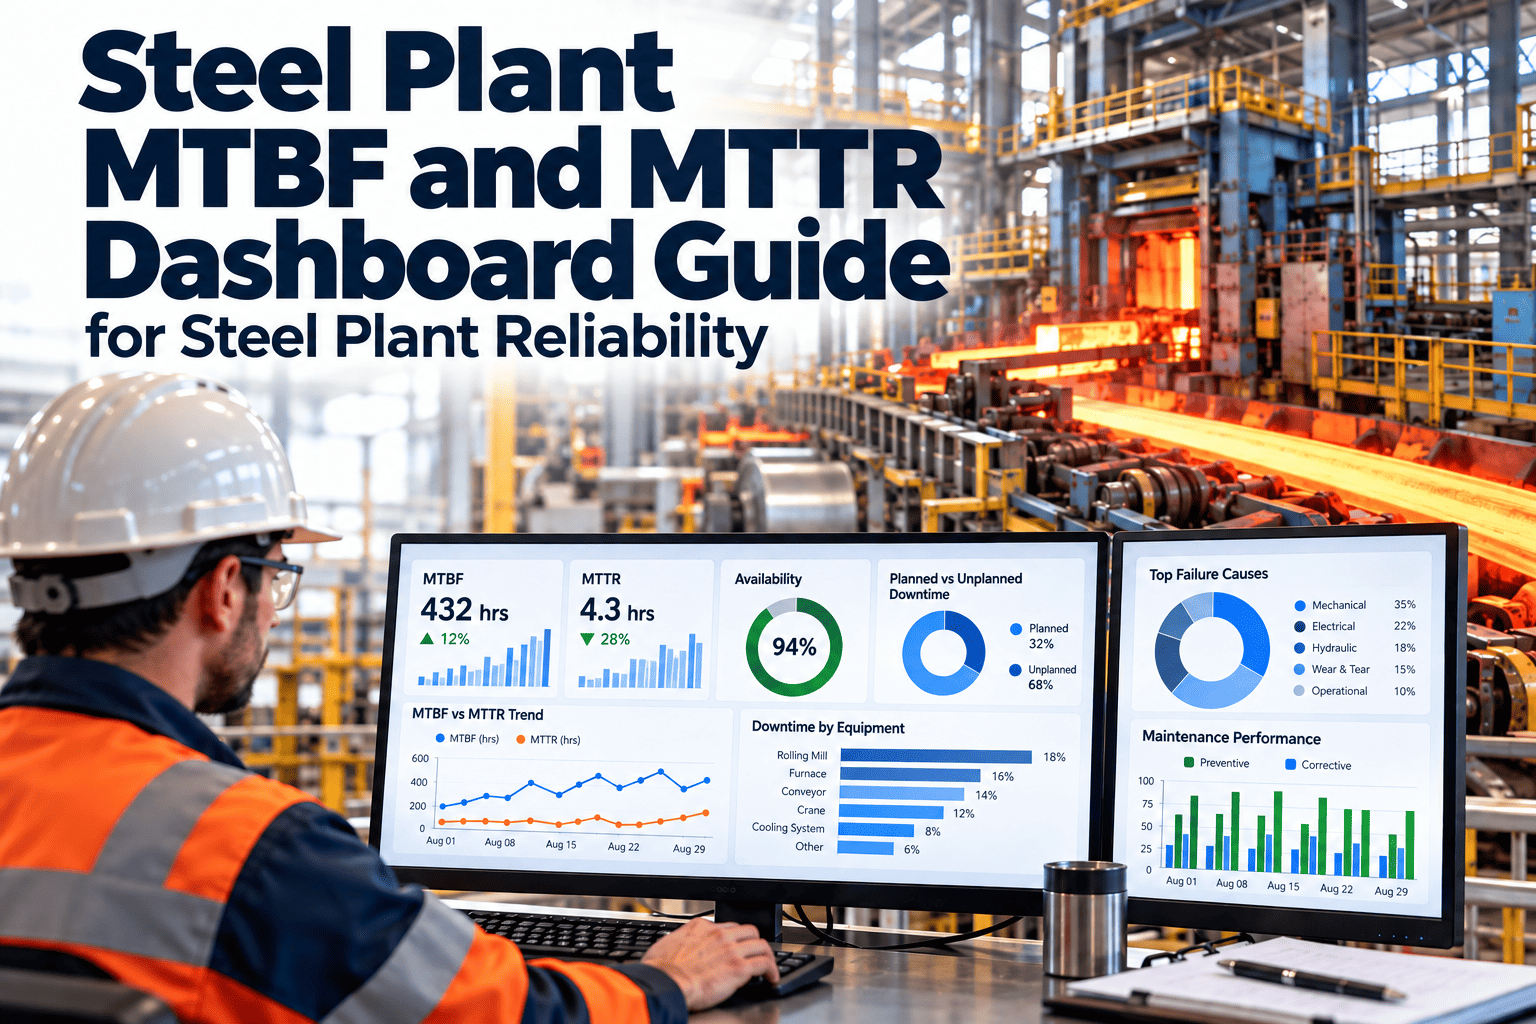
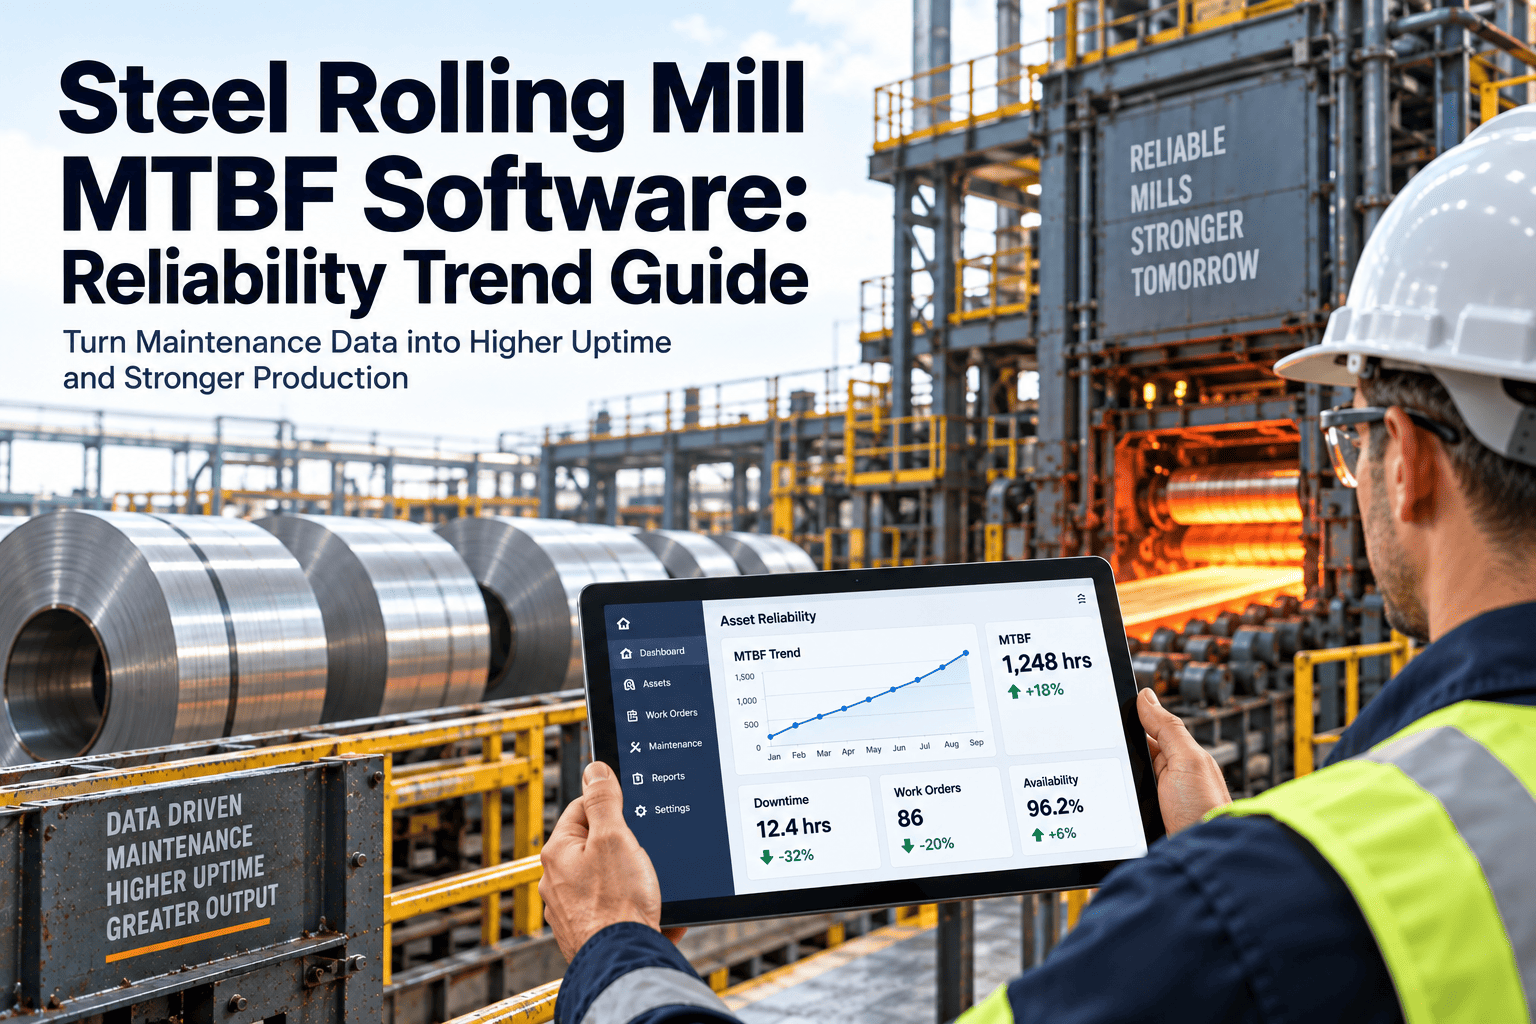
A ladle turret bearing seized twice in the same quarter at an integrated plant, and both times the repair itself only took three hours. What actually cost the plant two full shifts each time was everything around the repair — waiting for the fitter, waiting for the crane, waiting for a bearing that should have already been on the shelf. MTTR was never really about wrench time; it hides four separate stages, and most plants never find out which one is bleeding hours until they break the number apart. Getting that breakdown right, alongside a true MTBF trend, is what turns reliability tracking from a monthly report into a lever a plant can actually pull.
Steel Plant CMMS Guide 2026
MTTR & MTBF: Turning Two Numbers Into a Reliability Program
Blast furnace, caster, and steelmaking benchmarks — plus the four hidden stages inside every repair that determine your real MTTR.
The Four Stages Hiding Inside Every MTTR Number
"Repair time" is really four different clocks running one after another, and each one has a different fix. Attacking the average without knowing which stage is slow rarely moves the number.
1
Detect
Failure to notification. Condition monitoring cuts this from hours to minutes.
2
Respond
Notification to technician on-site. Mobile alerts beat radio and pager relays.
3
Diagnose & Repair
Active wrench time. Improved by SOPs, training, and correct-first-time parts.
4
Verify & Restart
Test run to full production. Standard restart checklists shorten this stage.
Most plants find the biggest leak sits in stage 1 or 2, not stage 3. Sign up free to see where yours does.
MTBF Benchmarks by Asset Class
MTBF targets are not universal; a healthy blast furnace pump and a healthy caster torch cutter live on completely different failure clocks. These ranges reflect well-maintained equipment in integrated steel plants.
| Area | Asset | Healthy MTBF Range |
|---|
| Blast Furnace | Cooling pumps | 8,000 - 15,000 hrs |
| Blast Furnace | Hot blast stove valves | 12,000 - 20,000 hrs |
| Blast Furnace | Charging system (bell/hopper) | 4,000 - 8,000 hrs |
| Steelmaking | BOF vessel tilting drives | 5,000 - 10,000 hrs |
| Steelmaking | Ladle turret | 3,000 - 6,000 hrs |
| Continuous Caster | Mold oscillation drives | 3,000 - 6,000 hrs |
| Continuous Caster | Spray cooling pumps | 6,000 - 12,000 hrs |
| Continuous Caster | Torch cut-off machines | 1,500 - 3,000 hrs |
Rolling Mill & Coil Handling MTBF Benchmarks
Downstream of the caster, failure clocks shift again. Roll-contact equipment on the hot side wears faster than the hydraulics and drives that support it, and vision-based inspection systems tend to be the most reliable link in the line.
| Area | Asset | Healthy MTBF Range |
|---|
| Hot Strip Mill | Roughing stand roll bearings | 2,500 - 5,000 hrs |
| Hot Strip Mill | Finishing stand hydraulic AGC | 4,000 - 8,000 hrs |
| Hot Strip Mill | Coilers | 3,000 - 6,000 hrs |
| Cold Rolling | Tandem mill drives | 5,000 - 10,000 hrs |
| Cold Rolling | Tension leveler | 4,000 - 7,000 hrs |
| Coil Handling | Overhead cranes | 6,000 - 12,000 hrs |
| Coil Handling | Vision-based defect inspection | 8,000 - 15,000 hrs |
See MTTR and MTBF Trended Per Asset, Automatically
Oxmaint pulls operating hours, failure events, and repair durations straight from work order data — no spreadsheets, broken down by stage and ready for your morning standup.
The Ladle Turret Bearing That Kept Coming Back
What Looked Fine
Two bearing failures in one quarter, both repaired in about three hours of active wrench time — a number that looked perfectly acceptable on its own.
What the Stage Breakdown Found
Total downtime per event ran closer to fourteen hours. The bearing itself sat off-site at a vendor, and the crane needed to lift the turret cover was booked out for other jobs both times.
What Changed
Turret bearings were reclassified as insurance stock on-site, and crane time was pre-booked into the PM calendar. The next failure was resolved in under five hours, start to finish.
Calculating MTTR and MTBF: A Worked Example
The formulas are simple, but plants often get tripped up on which hours to count. Here is a clean walk-through using one caster mold oscillation drive over a single quarter.
Quarter Data
Total operating hours4,500 hrs
Failures logged3
Repair durations2.5 hrs, 4 hrs, 3 hrs
MTBF4,500 ÷ 3 = 1,500 hrs
MTTR9.5 ÷ 3 = 3.17 hrs
Availability1,500 ÷ 1,503.17 × 100 = 99.79%
Two details usually cause bad numbers here: counting scheduled PM hours as failures (they should not be in the MTBF calculation at all), and stopping the MTTR clock at "repair complete" instead of "back to full production" — which skips the verify-and-restart stage entirely.
Five Root Causes Behind an Inflated MTTR
Once a plant splits MTTR into its four stages, the same handful of causes tend to show up in the detect and respond stages, well before a wrench ever touches the asset.
01
No spares on the shelf
Critical wear parts ordered after the failure, not before it, turning a repair into a procurement wait.
02
Inconsistent failure coding
The same root cause logged under five different labels, so recurring problems never surface in the data.
03
Manual notification chains
Operators calling a supervisor who then radios a planner who then pages a technician, adding minutes at every handoff.
04
No pre-approved SOP
Technicians troubleshooting from memory on a breakdown that has already happened a dozen times before.
05
Shared resource conflicts
Cranes, contractors, or specialist labor booked against other jobs at the exact moment a critical asset goes down.
Frequently Asked Questions
What is the difference between MTBF and MTTF?
MTBF applies to repairable assets like pumps and drives that return to service after failure. MTTF applies to non-repairable items like seals or fuses that get replaced, not repaired.
What MTTR should a critical steel plant asset target?
Most plants target under 2 hours for critical line equipment and 4 to 6 hours for non-critical assets.
Book a demo to see targets by your asset class.
Does scheduled PM downtime count against MTBF?
No. MTBF only counts unplanned failures and the operating hours between them, so it reflects true reliability rather than how often a schedule calls for downtime.
Why does MTTR sometimes look good while downtime is still high?
Standard MTTR often measures only active repair time, missing the detect and respond stages before a technician even starts work — which is frequently where most of the real delay lives.
How much MTBF data is needed before the trend is reliable?
A rolling twelve months or at least ten failure events, whichever comes first, is usually enough to separate a real reliability trend from normal variation between failures.
Should MTTR be tracked per asset or per plant?
Per asset class. A plant-wide average blends fast, low-consequence fixes with slow, high-consequence ones, which hides the exact failures that matter most.
Can a CMMS calculate MTTR and MTBF automatically?
Yes, Oxmaint computes both from work order timestamps automatically, broken down by failure code and asset class.
Sign up to see your current numbers.
Stop Averaging Away the Real Problem
Break MTTR into its real stages and trend MTBF against the right benchmark for every asset class, not a plant-wide guess.