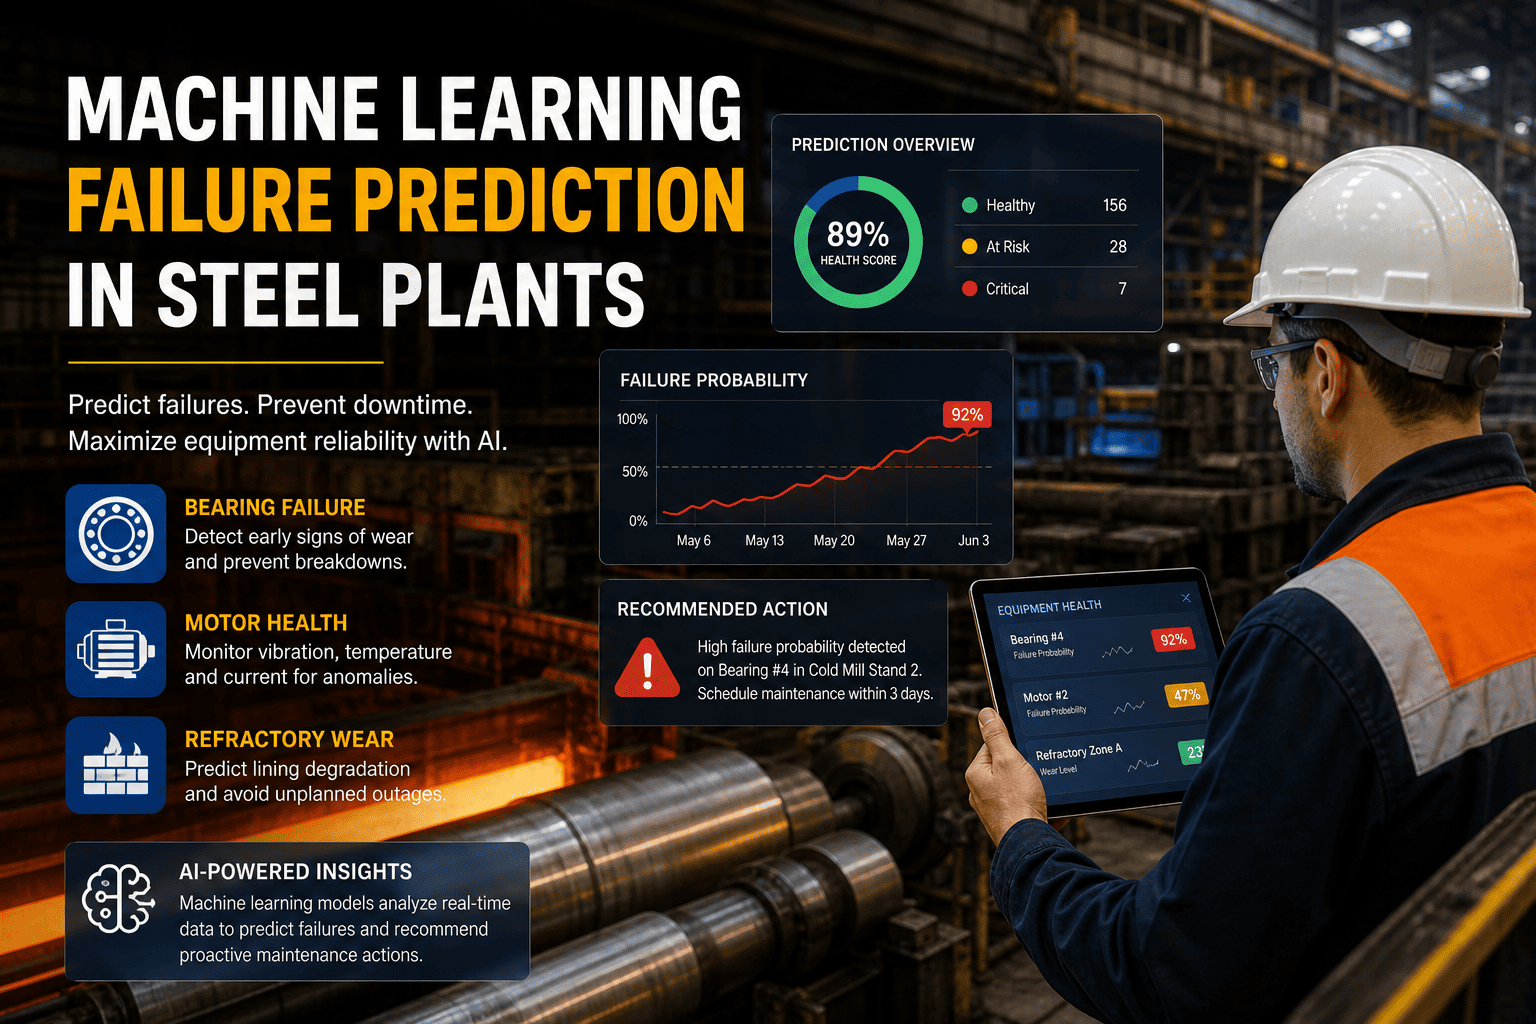
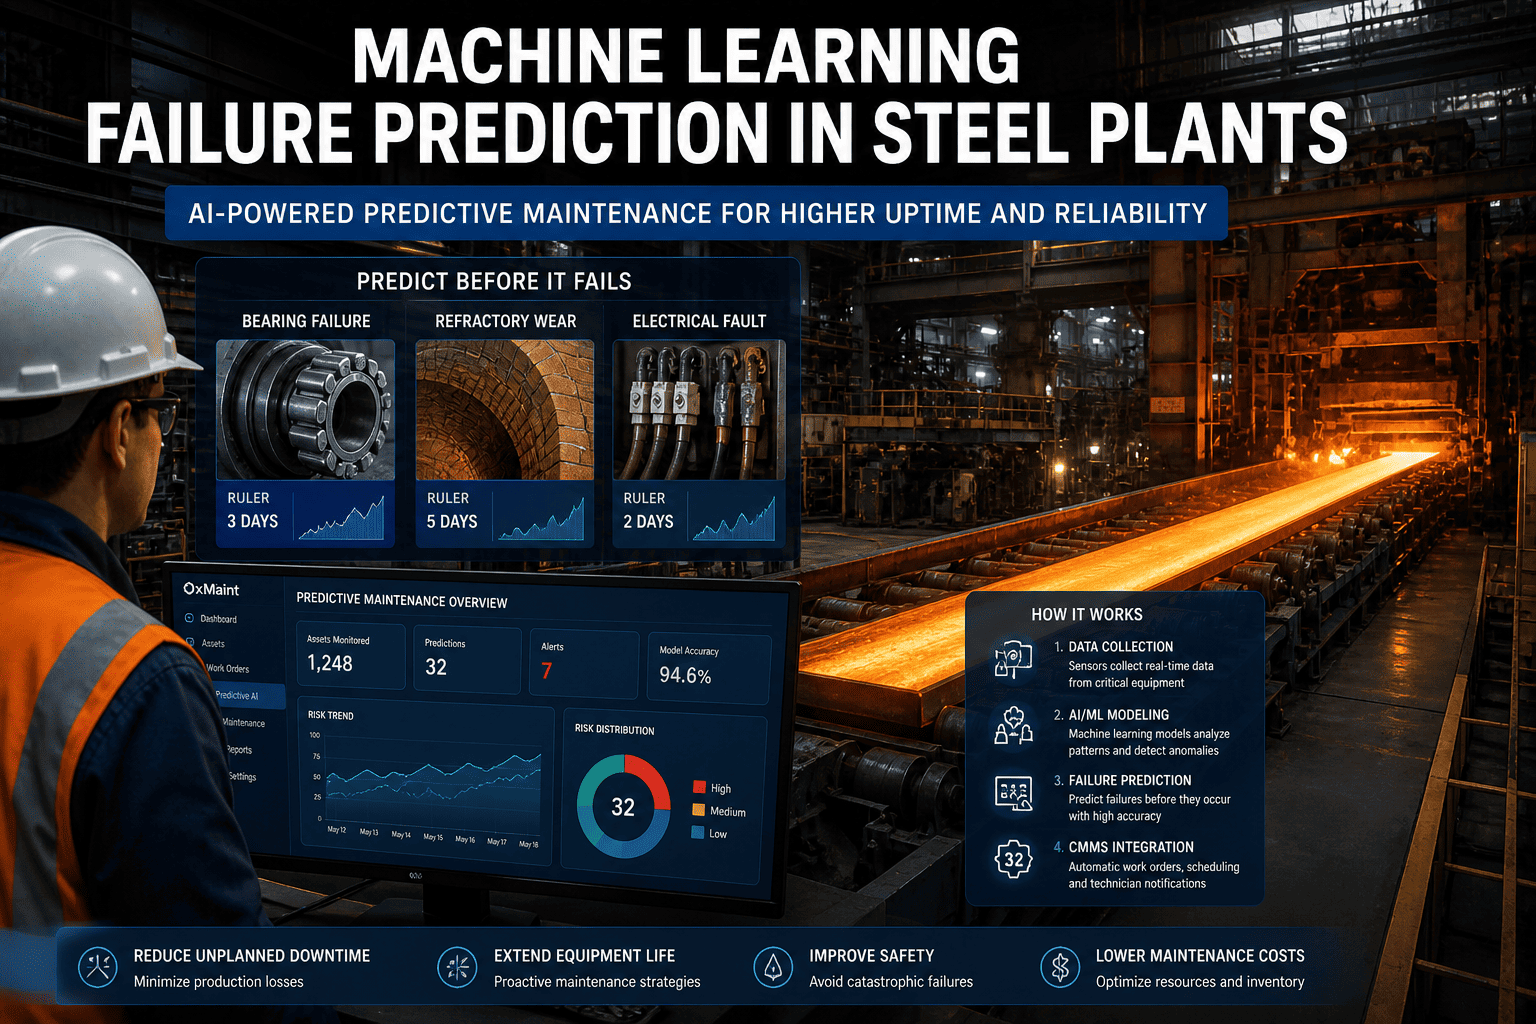
Machine learning can warn a steel plant about a failing gearbox or fan weeks ahead, but only if the plant can feed it clean sensor data and trustworthy failure history. Many projects stall not because the algorithm is weak, but because the labels are vague, the asset names do not match and nobody recorded what was actually repaired. This guide explains how failure prediction works, what AI readiness really means and how to prepare maintenance data first. It also shows where a CMMS for steel plants supplies the records that models need.
AI and Data
Steel Plant Machine Learning Failure Prediction for Predictive Analytics
Prepare sensor data, failure labels and feedback loops so machine learning can predict real equipment problems instead of producing noise.
DataSensors, process, work orders
FeaturesTrends, ratios, health indicators
ModelAnomaly or failure prediction
AlertRanked, with a reason
Action and feedbackWork order and outcome recorded
What machine learning can and cannot do for maintenance
Setting realistic expectations early prevents disappointment later. Machine learning is a tool for finding patterns, not a source of certainty.
What it can doSpot unusual behavior that people would miss across hundreds of signalsRank assets by how far they have drifted from normalEstimate how likely a known failure mode is within a time windowLearn from repeated failures and improve with feedback
What it cannot doPredict failure modes that never appear in the dataWork well on broken sensors or mislabeled historyReplace engineering judgment about cause and repairCreate value if no one acts on the alert
Frame the prediction question first
The same data can answer very different questions. Pick the one that matches a decision your team actually makes.
| Question | Approach | Needs | Fits when |
|---|
| Is this asset behaving unusually? | Anomaly detection trained on normal operation | Clean history of healthy running, few failure examples | Failures are rare or poorly recorded |
| Will this failure mode happen soon? | Classification over a defined time horizon | Labeled failure events with dates and modes | Repeated failures exist on similar assets |
| How much life is left? | Remaining useful life or survival models | Run-to-failure histories and usage data | Wear is gradual and measurable, such as bearings |
| Why is it drifting? | Contribution analysis and rules combined with engineering review | Process context and maintenance history | Teams need an explanation, not only a score |
AI readiness: where most steel plants actually stand
Readiness is about foundations, not enthusiasm. Use the ladder below to see which level your pilot assets have reached.
Level 1Fragmented. Paper or spreadsheet histories, inconsistent asset names and free-text failure notes.
Level 2Structured. A CMMS with a clean asset hierarchy and work orders, but limited failure coding.
Level 3Connected. Sensor tags mapped to assets, coded failures and reliable timestamps.
Level 4Learning. Alerts, inspections and repair outcomes are captured and used to retrain and review models.
Start with the records your models will learn from
Set up a clean asset hierarchy and structured work orders, and give future analytics a reliable base.
The label problem: turning work orders into training data
A model learns from examples of failure, so each example must say what failed, when and why. Poor labels are the most common hidden flaw.
Weak labelRoll stand problem fixedDate: closure date onlyNo asset component, no cause
Usable labelAsset: stand drive gearboxProblem: high vibrationCause: bearing wearDates: first symptom, failure, repair
Label quality checks
- Dates. Record when symptoms started, not only when the repair finished.
- Granularity. Attach the failure to the component, not only the whole line.
- Consistency. Use a controlled list of problem, cause and remedy codes.
- Exclusions. Mark events caused by process upsets or operator actions, so they do not teach the wrong pattern.
Features: the signals models actually use
Raw sensor streams are rarely fed straight into a model. Engineers turn them into indicators that capture health.
VibrationOverall level, frequency bands and trends at bearing, gear and running-speed frequencies, which suggest wear or imbalance.
TemperatureAbsolute values, rate of rise and difference from sister assets, normalized for load and ambient conditions.
ElectricalMotor current, power factor and phase balance, which can show mechanical load changes and winding problems.
Hydraulic and flowPressure, flow and valve response time, useful for spotting leaks, wear and contamination effects.
Process contextSpeed, product, steel grade, campaign stage and load, so normal changes are not mistaken for faults.
Maintenance eventsRecent repairs, lubrication, replacements and settings changes, which reset baselines.
Choosing which assets to model first
Not every asset suits machine learning. Start where failure is costly, signals exist and similar machines give the model more examples.
| Asset group | Why it suits modeling | Typical data | Watch out for |
|---|
| Fans and blowers | Many similar units, clear vibration and temperature signatures | Bearing vibration, temperature, motor current | Dust buildup that changes balance without any mechanical fault |
| Gearboxes and drives | High repair cost and long lead times for parts | Vibration, oil temperature, load, oil analysis | Load changes between products that look like wear |
| Pumps | Frequent bearing and seal problems with measurable early signs | Pressure, flow, vibration, motor current | Operating off the pump curve, which mimics damage |
| Hydraulic units | Gradual degradation visible in pressure and response time | Pressure, temperature, valve response, filter condition | Contamination events that are not logged |
| Electrical equipment | Trends in temperature and insulation condition | Winding and oil temperature, current, partial discharge where measured | Rare failures that leave few examples |
From historian to model: the data plumbing
Much of the effort in a first project is plumbing. These steps decide whether the model sees data that means what you think it means.
Tag mappingEvery sensor tag must map to one asset and one measurement point. Tags that cannot be mapped are left out until fixed.
Sampling and alignmentSignals recorded at different rates need aligning to a common time base, with the method documented.
CleaningRemove frozen values, spikes from sensor faults and periods when the asset was stopped, but keep a record of what was removed.
NormalizationAdjust for load, speed and ambient temperature so the model compares like with like.
Event joiningJoin repairs, lubrication and replacements from the maintenance system so baselines reset at the right moments.
Making alerts explainable to engineers
A score on its own invites doubt. Engineers act faster when an alert shows what changed, where and how it compares with the past.
A useful alert showsThe asset, component and measurement that movedA trend chart against the normal range for the same operating stateSimilar past events and what was found thenThe suggested next check and who should do it
A weak alert showsA risk score with no reason attachedA message that names only the whole lineNo link to history or to the maintenance recordNo way to mark the outcome afterwards
A pilot outline in four stages
A pilot should answer a simple question: do alerts lead to earlier, cheaper repairs on the chosen assets? The stages below keep it focused.
1Prepare the foundationClean the hierarchy, map sensor tags, review failure history and agree which failure modes the pilot will target.
2Build baselines and test offlineTrain on past data, test on later periods and review results with the engineers who know the equipment.
3Run in shadow modeLet the model raise alerts without formal action, and record how each compares with what technicians find.
4Go live with a playbookConnect alerts to work orders, set response times and review accuracy and lead time on a fixed schedule.
Steel-specific challenges for failure prediction
Steel plants bring conditions that make generic models perform poorly. Plan for these early.
Changing operating regimesDifferent grades, speeds and campaign stages shift normal readings, so models must know the operating state.
Few failures per assetCritical equipment rarely fails, which leaves little data to learn from. Pooling similar assets and using anomaly detection helps.
Harsh sensing conditionsHeat, dust, scale and water damage sensors and cables, producing drift or dropouts that look like faults.
Repairs that change behaviorAfter a rebuild, an asset behaves differently. Without logged events, models treat the shift as degradation.
Preventive replacementParts removed before failure hide the failure signal, leaving models with few examples of end-of-life behavior.
Common modeling pitfalls
A model can look excellent in testing and fail in the plant. These are the usual reasons.
1Data leakageUsing information that would not be known at prediction time, such as the work order created after the failure.
2Class imbalanceFailures are rare, so a model that always predicts healthy looks accurate while being useless.
3Random train and test splitsTime-ordered data should be split by time, so tests mimic real use.
4Model driftEquipment, products and procedures change, so accuracy fades without review and retraining.
5Alerts without explanationIf engineers cannot see why an alert fired, they will stop trusting it.
Judging a model by maintenance outcomes
Accuracy alone is a poor measure. Judge the model on the trade-offs maintenance teams care about.
PrecisionOf the alerts raised, how many were real problems. Low precision wastes technician time.
RecallOf the real failures, how many were flagged beforehand. Low recall means missed warnings.
Lead timeHow early the warning arrived, compared with the time needed to plan the repair.
Cost of errorsWeigh a false alarm against a missed failure for each asset class, since they differ widely.
The feedback loop that keeps models useful
A model improves only when outcomes return to it. The loop below shows what must be recorded.
1Alert raised
2Technician inspects
3Finding recorded
4Work order closed with codes
5Outcome tagged true or false
6Model reviewed and tuned
Data readiness checklist for a pilot
AssetsOne hierarchy, one name per asset, sensor tags mapped to assets
TimeSynchronized clocks across sensors, historian and maintenance records
FailuresStructured problem, cause and remedy fields on corrective jobs
HistoryEnough operating history to cover seasons, products and campaigns
SensorsCalibration and health records, with faults flagged in the data
EventsRepairs, overhauls and setting changes logged with dates
PeopleA reliability engineer to review alerts and a planner to act on them
GoalA defined target and a decision rule for extending the pilot
Who does what in a prediction program
Models need people around them. Clear roles stop alerts from landing in a shared inbox where nobody owns them.
Reliability engineerChooses failure modes to target, reviews alerts, confirms diagnoses and decides when limits or models need tuning.
Data or analytics specialistBuilds and monitors models, checks data quality and documents how features and thresholds were chosen.
Maintenance plannerConverts confirmed alerts into work orders, checks parts and fits repairs into the next available window.
Technicians and operatorsInspect assets after an alert and record what they find, which becomes the label for future learning.
Plant leadershipSets the goal, protects time for reviews and decides when a pilot has earned wider rollout.
KPIs for a failure prediction program
Alerts confirmed by inspectionShows real-world precision.
Failures preceded by an alertShows how many problems were caught early.
Median warning lead timeCompared with typical repair planning time.
Closed jobs with complete codesMeasures training data quality over time.
Time from alert to decisionHighlights process delays after the model has done its part.
How Oxmaint supports machine learning readiness
Oxmaint maintenance management software does not replace a modeling platform. It supplies and organizes the maintenance records those models depend on.
Asset hierarchyA consistent structure that sensor data and failures can attach to.
Structured work ordersRecord problem, cause, action and dates at closure.
Mobile inspectionsConfirm or reject alerts in the field with readings and photos.
Condition-based triggersCreate jobs from readings that cross defined limits.
Preventive historyKeep a dated log of lubrication, replacements and overhauls.
ReportingReview failure frequency, repeat issues and data completeness.
Questions to settle before trusting a model
Use these questions in a review meeting before alerts are allowed to trigger real work.
- What failure mode is it meant to catch? A model with no named target is hard to judge.
- How was it tested? Results should come from later periods, not a random mix of past data.
- What happens after a false alarm? Agree the cost of a wasted inspection and who accepts it.
- Who retrains it, and when? Name an owner and a review date after process or equipment changes.
- How will outcomes be recorded? Without a clear field for true or false results, learning stops.
Frequently asked questions
How much failure data do we need?It depends on the method. Anomaly detection needs mostly healthy data, while failure classification needs many labeled events.
Can we start with few failures?Yes. Start with anomaly detection and condition rules, and build failure history as you go.
Why do models lose accuracy over time?Equipment, products and procedures change, so models need review and retraining with recent outcomes.
Can I see how work orders feed analytics?A demo can show coded closure and reporting. Book a walkthrough.
Give your prediction models a maintenance history they can trust
Capture structured failures, inspections and outcomes today, and every repair will make tomorrow's predictions better.