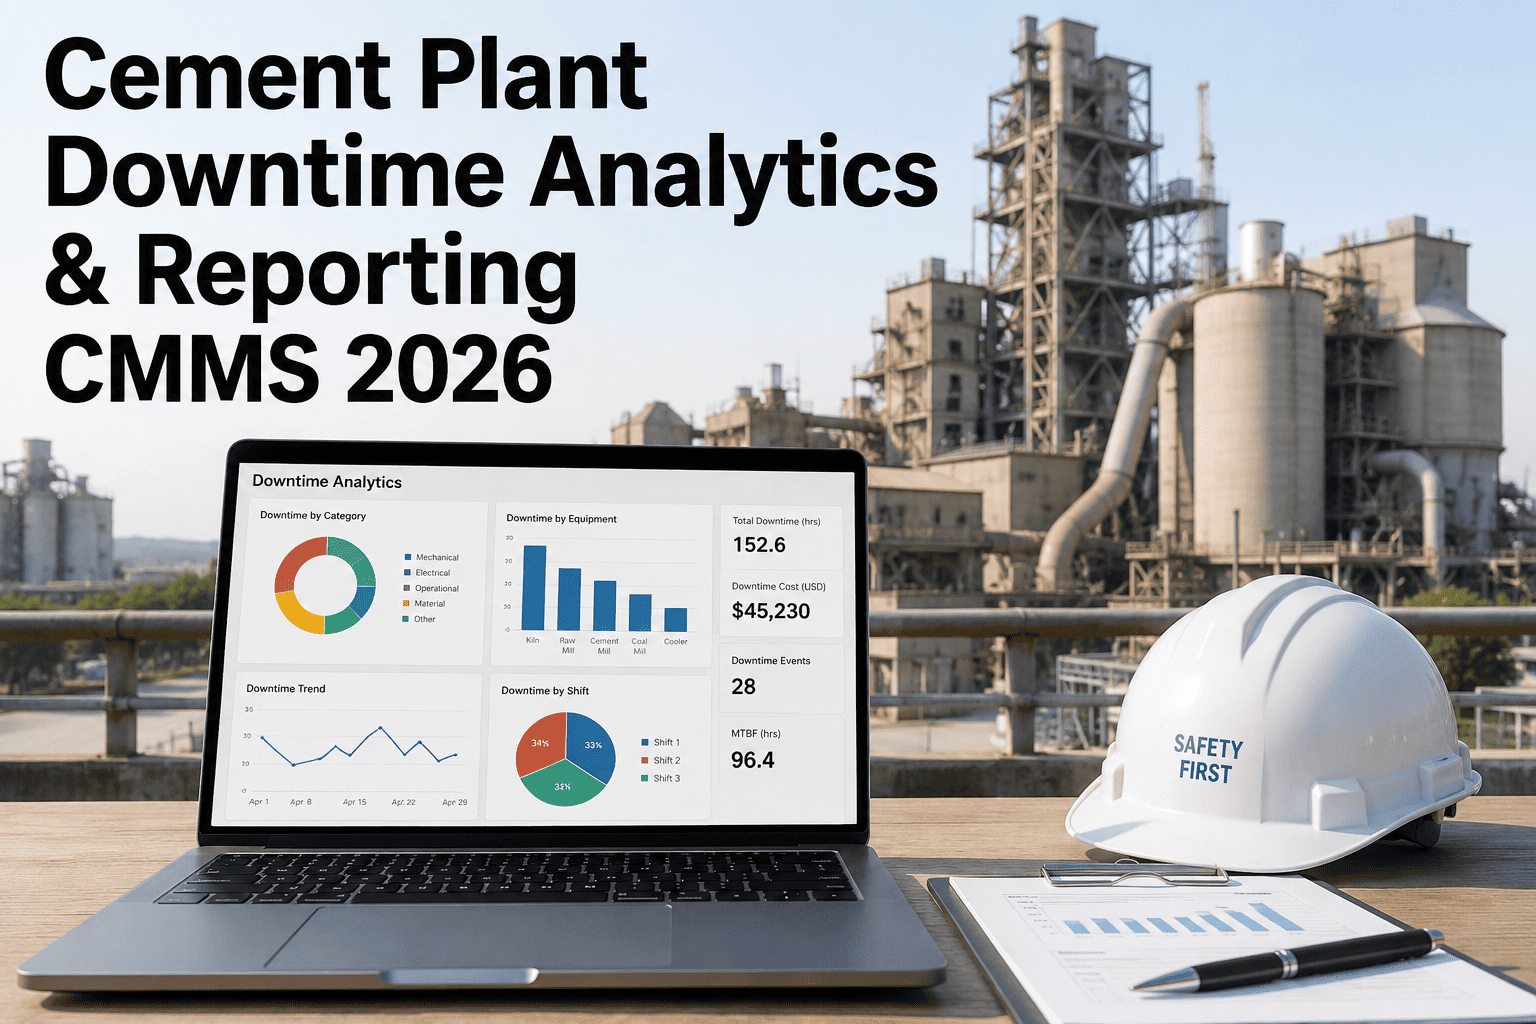
Cement production loses an estimated 8–12% of available operating hours every year to unplanned downtime, and a single kiln stop can cost $40,000–$120,000 per day in lost clinker output, fuel waste, and restart energy. Downtime analytics — knowing precisely where those hours went and why — is the dividing line between a reliability program that compounds and one that drifts on gut feel. This 2026 CMMS guide breaks down the taxonomy, data capture, dashboard design, and automated reporting that turns raw downtime events into prioritized action. If you want to skip ahead and instrument your own plant, you can Start Free Trial and begin importing event logs in under an hour.
Where did the last 4,200 production hours actually go?
In a typical 1.8 MTPA cement plant, unplanned downtime silently consumes 600–1,100 hours per year across the kiln, raw mill, and finish mill. Without a structured analytics layer, 70% of those hours get bucketed as "miscellaneous" or "process." This guide shows how a modern CMMS turns that fog into a Pareto, a cost trend, and a weekly action list.
Why 70% of cement downtime is mislabeled
When an operator logs "kiln down — fan issue" without a structured failure code, the data is nearly useless for trend analysis. Most plants discover this only when a $2M refractory rebuild arrives two years early.
Consider a mid-size 180-asset plant spending roughly $42,000 a year on spreadsheet-based downtime reporting. Three reliability engineers dedicate 6–8 hours weekly to reconciling shift logs, and the resulting "report" lands on the plant manager's desk 11 days after month-end. By the time the Pareto is reviewed, the failure mode has already recurred twice. A CMMS with automated downtime capture collapses that lag from 11 days to under 4 hours — and shifts the engineer's time from data wrangling to RCA.
A failure-mode taxonomy built for cement assets
ISO 14224 and ISO 55000-aligned taxonomies give you apples-to-apples comparison across kiln lines, raw mills, and finish mills. Below is the cement-specific breakdown we recommend inside a CMMS.
- Refractory brick fallout / hot face spall
- Tire & roller wear — axial float alarm
- ID fan vibration / bearing temperature
- Coating ring formation (burn zone)
- Burner pipe deformation / tip loss
- Table liner / roller tire wear progression
- Separator cage bearing failure
- Mill main gearbox oil contamination
- Hydraulic tension system leak
- Feeder jam / moisture surge blockage
- Diaphragm slot plugging
- Cement silo aeration pad failure
- Packer valve sticking / dust ingress
- Conveyor belt tear at transfer point
- Compressed air pressure drop (drier)
Without this taxonomy, a "gearbox issue" on the raw mill and a "gearbox issue" on the kiln girth drive look identical in the dashboard — even though one costs $18K/day and the other risks a $1.4M rebuild. The taxonomy is the single highest-leverage setup step in any CMMS downtime rollout.
From shift logbook to automated event stream
Downtime data quality is decided in the first 90 seconds of a stop. Manual end-of-shift logs lose 35–50% of micro-stops under 5 minutes. Here is the capture hierarchy we deploy.
The kiln, mill, and fan motor amps feed into the CMMS via OPC-UA or MQTT. Any deviation beyond configured thresholds opens a downtime event automatically, stamped to the second. Captures 100% of stops >30 seconds with zero operator input.
For events requiring human context (e.g., "coating ring — manually cleared"), the shift operator picks from a constrained 3-level failure tree on a rugged tablet at the control room. Average entry time: 42 seconds. Eliminates free-text "miscellaneous" buckets.
When the work order closes, the technician attaches failure mode, root cause, and corrective action — coded to ISO 14224. This is what turns a downtime row into a reliability improvement signal.
Reliability engineer reviews open events, confirms cost allocation, and locks the week. The 15-minute review replaces the old 6-hour spreadsheet grind.
The kiln downtime Pareto that changes the weekly meeting
A correctly built Pareto doesn't just rank failure modes — it ranks them by cost-weighted hours, not raw duration. That distinction is what moves a plant from "busy" to "effective."
The top two modes — ID fan vibration and coating rings — drive 54% of annual kiln downtime hours and roughly $1.9M in lost margin. Both are detectable 7–14 days before failure with vibration trending and shell-scan thermography. That is the meeting-changing insight.
After CMMS rollout in July, monthly kiln downtime cost dropped 65% by December — driven by predictive alerts on ID fan bearings and a coating-ring flush protocol triggered by shell-thermography trends.
How to calculate the true cost of every downtime hour
Most plants still calculate downtime cost as (hours × clinker rate × margin). That misses restart fuel, refractory thermal-shock damage, and lost grind capacity downstream. Here is the formula we embed in the CMMS.
Worked example: a 6-hour kiln stop caused by ID fan bearing failure. H=6, R=145 tph, M=$28/t, Fr=$8,400, Rx=$2,200, Cu=$1,600, Id=$3,100. The naive calculation gives $24,360. The CMMS-calculated TDC is $39,660 — 63% higher. That gap is where reliability investment decisions actually live.
| Metric | Before (Manual Logs) | After (CMMS Analytics) | Delta |
|---|---|---|---|
| Annual unplanned downtime (kiln + mills) | 1,040 hrs | 612 hrs | −41% |
| Reporting lag (event → reviewed) | 11 days | <4 hours | −98% |
| Engineer hours/week on reporting | 22 hrs | 4 hrs | −82% |
| Uncoded downtime events | 25% | 3% | −88% |
| Annual downtime cost (plant-wide) | $3.1M | $1.8M | −$1.3M |
| CMMS subscription + implementation | — | $58K/yr | — |
| Net year-one payback | — | — | $1.24M |
Five tiles every cement plant manager should see at 7 a.m.
A dashboard that shows 40 KPIs shows nothing. The most effective cement-plant downtime dashboards we deploy have five tiles, each answering one question with one number and one trend sparkline.
OEE-aligned availability across kiln, raw mill, finish mill. Target ≥ 92%.
Current #1 cost-driver with 14-day vibration trend and next-inspection date.
Mean time between failures across the 12 critical tagged assets. Rising = good.
Corrective actions from last week's downtime review, with owner and due date.
Live tally of TDC across all tagged assets versus monthly budget of $140K.
From the control room to the boardroom
"We cut uncoded downtime from 31% to under 4% in one quarter. The kiln Pareto finally changed the conversation in our Monday meeting — we stopped arguing about what happened and started deciding what to fix."
"The automated cost calculation was the unlock. When we showed the CFO that a $14K bearing replacement would avoid a $96K kiln stop, the predictive maintenance budget approval took 20 minutes instead of 6 months."
Stop guessing where the hours went.
Deploy a CMMS that captures every stop, costs every hour, and ships the Pareto before your Monday meeting starts.
Cement downtime analytics — answered
Turn every downtime hour into a decision.
Join the cement plants that replaced 11-day spreadsheet reports with a 4-hour automated Pareto. Your Monday meeting will never be the same.
Free 14-day trial · No credit card